Infinite-Uptime

Author: Iu_Zer0

  • Your Crane Is Already Going Down. You Just Don’t Know It Yet!!

    Your Crane Is Already Going Down. You Just Don’t Know It Yet!!

    Your Crane Is Already Going Down. You Just Don’t Know It Yet!!
    Why standard PdM was never built for cranes — and why the sensors you trust most are silent exactly when faults emerge.

    Read Time: 8–9 minutes | Author – Chaiitanya Bulusu Your Crane Is Already Going Down. You Just Don't Know It Yet!!
    Key highlights

    • You are managing the most complex and costly asset on the plant floor. Crane downtime is an operations problem — the cascade cost dwarfs the repair bill by 10–15×.
    • The tools you trust most have a structural blind spot. Battery-based PdM(Predictive Maintenance) sensors sample too rarely, stop recording under load, and fail in foundry heat — missing faults exactly when they emerge.
    • The gap is 3–4 weeks of fault progression your current system cannot see. By the time a vibration alarm fires on a time-sampled sensor, the bearing is already failing.
    • Crane AI Shield from Infinite Uptime is purpose-built for this environment. RPM-gated FFT, always-on monitoring, and IP68 hardware that survives where battery sensors burn out — with 99.97% validated uptime accuracy.
    • 5-day deployment. 6–12 month ROI payback. Up to 99% prescription adoption rate. Outcomes validated — not just predicted.

    What is Crane AI Shield?

    Crane AI Shield is an always-on, crane-specific AI monitoring solution that detects developing mechanical faults under real operating conditions and delivers evidence-backed maintenance prescriptions before failures cause unplanned downtime.

    You are the reliability manager. The plant maintenance head. The person who knows that when the ladle crane goes down mid-shift with no warning, the bay stops, the heat schedule collapses, and your phone rings before the crane does.


    You have monitoring in place. You have schedules, sensors, and inspection routes. And yet, right now, a fault is developing inside your crane’s gearbox that your current sensor cannot detect.


    Not because it hasn’t alarmed yet. Because it physically cannot alarm. The sensor sampled at 6 AM. The fault emerged at 2 PM — under load, when the crane was working hardest. The sensor was asleep.


    This is the sampling gap. And it is costing you downtime you cannot see coming.

    “Standard PdM was never built for cranes. The sensor sleeps while the crane works — and faults reveal themselves exactly at the moment the sensor is silent.”

    — Infinite Uptime, Crane AI Shield

    What you are responsible for protecting

    Before we get to the monitoring gap, let’s be clear about what is actually at stake. In steel mills and mining operations, cranes are not auxiliary equipment — they are the production flow. When the main hoist fails, the bay stops. The cost compounds within hours.


    When the crane goes down, it doesn’t produce a maintenance work order. It produces a cascade.

    $10K–50K[1]
    per hour, lost productivity
    Steel mills & Mining
    3–5×[2]
    reactive vs planned repair cost
    Emergency mobilisation
    $75K–$250K[3]
    all-in cost, one hoist failure
    Emergency repair + lost production
    8 of 10[3]
    breakdowns eliminated
    Converted to planned maintenance

    Crane AI Shield does not replace your expertise. It closes the gap your current sensors leave open.

    You know your cranes. You know your plant. What you need is a system that captures vibration data exactly when faults emerge — under load, at stable speed, in the harshest environment on your site — and translates that data into specific, evidence-backed actions your team can execute on shift. That is what Crane AI Shield is built to do.

    Not another dashboard. Not another time-sampled alert. A prescription: which bearing, which gear, which shift to schedule it — with the FFT spectrum and trend data to justify the intervention.

    The repair cost is the smallest number on the incident report. The real cost is the 24–72 hours of bay downtime, the emergency parts at premium pricing, the overtime labour, and the cascading damage — a $5K bearing fault that takes out the gearbox, motor, and shaft, turning a small repair into a $500K incident.

    Cost component Estimated impact per event
    Emergency repair premium (parts + rigging + overtime) $30K–$80K
    Lost production — bay idle during repair 24–72 hrs
    Cascading damage — bearing fault → gearbox → motor → shaft Up to $500K
    Safety investigation + adjacent crane halt Variable — hours to days

    Source: [1] Mazzella Companies; [3] Infinite Uptime ROI Estimate 2026. Actual costs vary by facility size and crane criticality.

    The tool you trust has a structural blind spot

    You have predictive maintenance in place. The problem isn’t effort or investment. The problem is that the sensor technology underlying standard PdM(Predictive Maintenance) was not designed for cranes — and in three specific ways, it fails at exactly the moment you need it most.

    01
    You miss the
    moments that matter
    Battery sensors only wake a few times a day. Most faults reveal themselves between samples — and you never see them.
    02
    No data when the
    crane is working
    Standard sensors stop recording exactly when the asset is loaded — the moment faults actually emerge. The crane works hardest. The sensor is asleep.
    03
    Sensors die before
    they can warn you
    Sealed battery units crumble under foundry heat, dust, and vibration. By the time the sensor fails, the bearing already has — and you had no warning from either.

    The structural problem runs deeper than sensor quality. Every approach your team currently uses shares the same limitation: it reacts to failure signals rather than tracking degradation continuously.

    What you’re currently using What it captures The gap it leaves
    OEM scheduled intervals Average component life at standard conditions Actual degradation rate under your duty cycles — heat, load, speed, environment
    Battery PdM sensors Vibration snapshots at scheduled intervals — a few times per day Faults that develop between samples and under load — precisely when cranes are most stressed
    Operator observation Visible or audible failure symptoms Early-stage bearing and gear degradation — weeks before it becomes observable
    PlantOS™ Crane AI Shield RPM + temperature streaming 24/7. FFT triggered at stable speed under load Nothing — always-on coverage exactly when faults emerge

    Vibration-based systems can identify bearing and gearbox degradation 2–6 weeks before catastrophic failure[4] — but only when the sensor is capturing data at the moment the fault signal exists. A sensor that sleeps through the fault cannot catch it.

    What your crane is actually dealing with — and why it matters

    The sampling gap hits hardest in the two environments where Crane AI Shield operates. In steel mills and mining operations, cranes run the most demanding duty cycles in heavy industry — and bearing and gearbox faults develop faster, more unpredictably, and with higher consequence than in any standard industrial environment.

    Steel mills: ladle cranes and casting cranes

    A ladle crane in a BOF or EAF shop runs in one of the harshest industrial environments on earth — sustained radiant heat from molten steel at 1,600°C, heavy shock loading on every lift, and back-to-back duty cycles with minimal rest between heats. These conditions accelerate bearing wear, gear mesh degradation, and motor winding fatigue at rates that OEM maintenance intervals were never calibrated for.

    The problem with standard battery PdM in this environment is threefold. First, battery units degrade rapidly under sustained radiant heat — the sensor fails before the bearing does. Second, the most destructive loading events happen during the lift itself, precisely when a time-sampled sensor is between snapshots. Third, the high-shock, high-duty-cycle profile of a ladle crane means bearing defects progress from incipient to catastrophic in days — not weeks.

    Crane AI Shield captures 3-axis vibration, temperature, and RPM continuously from sensors rated to 180°C surface temperature. FFT analysis triggers only when the motor is in a stable RPM band — under load, capturing the fault signature at its clearest, not during accel/decel noise.

    Mining: overhead cranes in concentrators and crushers

    In copper, gold, and iron ore processing, overhead cranes in concentrator buildings and crusher halls run high duty cycles in extreme particulate environments. The combination of continuous operation, abrasive dust ingress into bearing housings, and the physical consequence of a main hoist failure — stopping maintenance access to the entire grinding and flotation circuit — makes these cranes among the highest-risk assets on any mine site.

    Battery sensors in crusher hall environments face compounding failure modes: particulate contamination of the sensor housing, adhesive mount degradation under vibration, and sampling schedules that have no relationship to when the crane’s bearing loads are highest. A wheel-bearing failure on an overhead crane idles the whole concentrator bay. A hoist gearbox failure with no advance warning turns a $5K bearing replacement into a $500K multi-component rebuild at height.

    Crane AI Shield’s IP68 SS316 enclosures and stud-mounted wired sensors are designed specifically for this environment — no adhesive mounts, no batteries, no wireless signal dropout in high-RF industrial buildings.

    Your guide to closing the blind spot: Crane AI Shield

    Crane AI Shield does not replace your expertise. It closes the gap your current sensors leave open.

    You know your cranes. You know your plant. What you need is a system that captures vibration data exactly when faults emerge — under load, at stable speed, in the harshest environment on your site — and translates that data into specific, evidence-backed actions your team can execute on shift. That is what Crane AI Shield is built to do.

    Not another dashboard. Not another time-sampled alert. A prescription: which bearing, which gear, which shift to schedule it — with the FFT spectrum and trend data to justify the intervention.

    The fault coverage map: what Crane AI Shield detects

    Across three coverage tiers, Crane AI Shield monitors up to 19 failure modes on the main hoist drive train and long-travel wheel systems — all mechanical faults that standard battery PdM either misses between samples or fails to detect under load.

    Coverage tier Fault / fault mode Detected by Detection method
    Starter + Standard Gear tooth wear ✓  Crane AI Shield Gear-mesh frequency (GMF) analysis
    Starter + Standard Gear backlash ✓  Crane AI Shield GMF sidebands
    Starter + Standard Misaligned gears ✓  Crane AI Shield Spectral analysis
    Starter + Standard Cracked / broken gear teeth ✓  Crane AI Shield Cepstrum + shock pulse
    Starter + Standard Inadequate gear lubrication ✓  Crane AI Shield GMF amplitude trending
    Starter + Standard Inadequate bearing lubrication ✓  Crane AI Shield High-frequency envelope analysis
    Starter + Standard Rolling-element bearing defects (BPFO/BPFI/BSF) ✓  Crane AI Shield FFT fault frequency mapping
    Standard only Structural looseness / soft-foot ✓  Crane AI Shield Sub-synchronous vibration
    Standard only Rotating looseness ✓  Crane AI Shield Harmonic spectrum analysis
    Standard only Unbalance ✓  Crane AI Shield 1× RPM amplitude
    Standard only Bent shaft ✓  Crane AI Shield 1× + 2× RPM
    Standard only Rotor bow & rub ✓  Crane AI Shield Sub-synchronous + 1×
    Standard only Cracked / loose rotor bars ✓  Crane AI Shield Motor current + vibration
    Standard only Coupling faults ✓  Crane AI Shield 2× RPM sidebands
    Standard only Shaft misalignment ✓  Crane AI Shield Axial + radial vibration
    Standard only Pedestal bearing looseness ✓  Crane AI Shield Harmonic series
    Comprehensive only Wheel-bearing lubrication degradation ✓  Crane AI Shield High-frequency envelope
    Comprehensive only Rolling-element wheel-bearing defects ✓  Crane AI Shield FFT + wheel RPM
    Comprehensive only Wheel unbalance ✓  Crane AI Shield 1× wheel RPM
    Comprehensive only Wheel-side rotating looseness ✓  Crane AI Shield Harmonic series

    Starter: 7 failure modes (main hoist gearbox only)   |   Standard: 19 failure modes (full hoist drive)   ★ Recommended   |   Comprehensive: 19 + wheel systems


    Fault Detection Gap — Steel & Mining Crane Operations


    Fault Severity (%)


    Fault severity (%)

    Crane AI Shield detection point

    Traditional monitoring (failure event)


    The PlantOS™ Architecture: from signal to prescription

    Crane AI Shield is built on a three-tier architecture designed specifically for cranes — continuously moving assets that need wired, always-on instrumentation and RPM-synchronised data capture. Every design decision responds directly to the three failures of standard battery PdM.

    Tier 1 : Signal Acquisition — what goes on your crane
    01

    Primary sensor: IP68 SS316 unit mounted on the AC motor — captures 3-axis vibration, temperature, and RPM in a single rugged node. 180°C-rated cabling. No batteries. Stud or bracket mount. Secondaries on gearbox stages and drum bearings flow data in a strict primary–secondary RPM-synchronised loop. Survives where battery sensors burn out.

    Tier 2 : Edge Processing and Transmission
    02

    Primary sensor: IP68 SS316 unit mounted on the AC motor — captures 3-axis vibration, temperature, and RPM in a single rugged node. 180°C-rated cabling. No batteries. Stud or bracket mount. Secondaries on gearbox stages and drum bearings flow data in a strict primary–secondary RPM-synchronised loop. Survives where battery sensors burn out.

    Tier 3 : AI Engine and Prescription Delivery
    03

    Primary sensor: IP68 SS316 unit mounted on the AC motor — captures 3-axis vibration, temperature, and RPM in a single rugged node. 180°C-rated cabling. No batteries. Stud or bracket mount. Secondaries on gearbox stages and drum bearings flow data in a strict primary–secondary RPM-synchronised loop. Survives where battery sensors burn out.

    A Crane AI Shield prescription does not say ‘check gearbox.’ It says: “Gearbox vibration at MDE bearing trending 23% above baseline over 14 days. BPFO frequency signature indicates outer race wear. Recommend bearing inspection within 7 days. Evidence: trend chart, FFT spectrum attached.” That is actionable. That is why up to 99% of prescriptions are acted upon.

    The 99% Trust Loop — your guarantee, not just a feature

    Most industrial AI generates alerts. The bottleneck has never been detection accuracy — it has been execution. You’ve seen alert fatigue. Your team gets a notification, investigates, finds nothing actionable, and gradually stops trusting the system. PlantOS™ is built around the 99% Trust Loop™ — a validated cycle where every prescription is specific, evidence-backed, and contextually grounded.
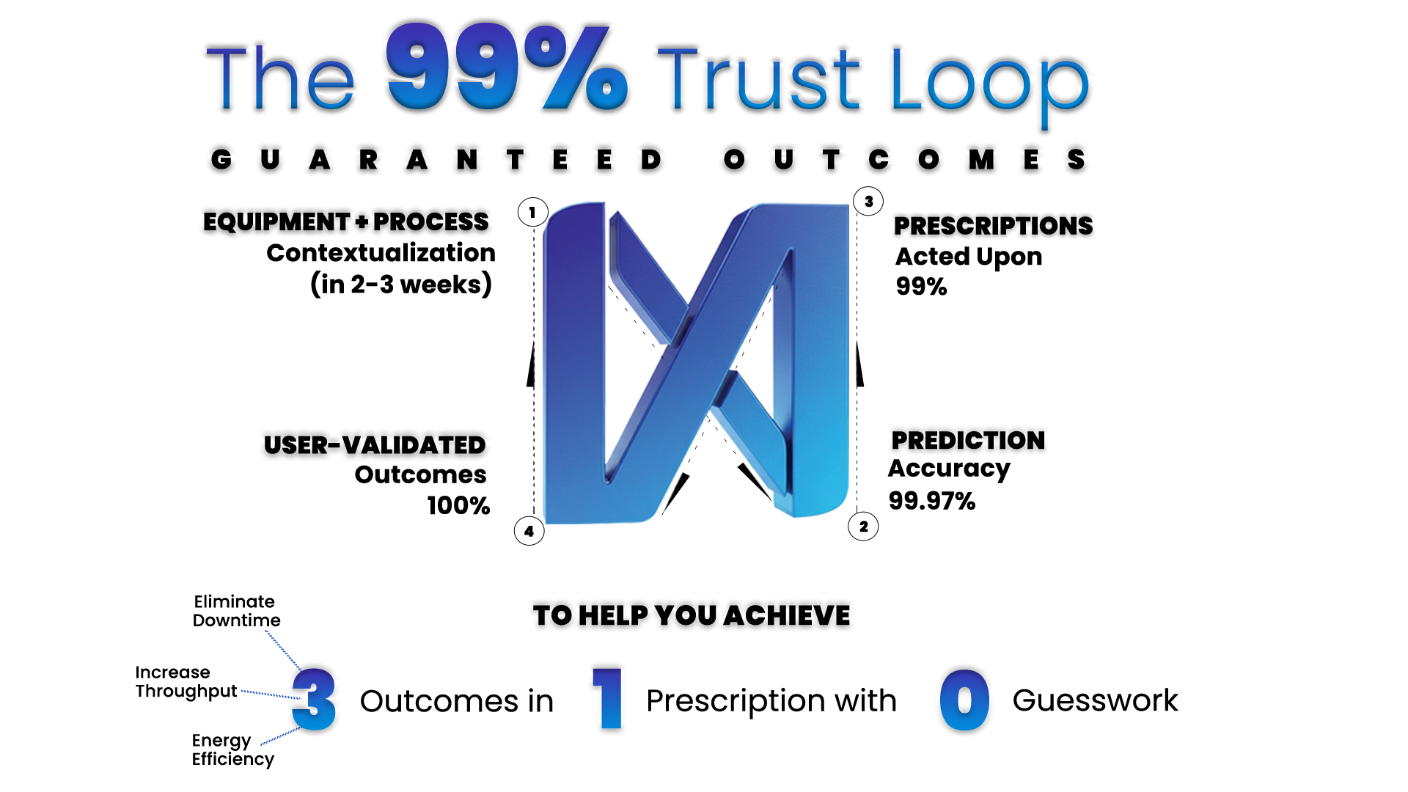
    Infographic titled "The 99% Trust Loop: Guaranteed Outcomes." A central blue 3D "N" icon is surrounded by a four-step cycle: 1. Equipment + Process Contextualization, 2. 99.97% Prediction Accuracy, 3. 99% Prescriptions Acted Upon, and 4. 100% User-Validated Outcomes.

    01

    Equipment
    Contextualization


    Your crane’s kinematic profile, gear-mesh frequencies,
    shaft orders, and duty cycle mapped before any inference.
    Context-free alerts are the source of false alarms and
    alert fatigue.

    02

    Prediction
    Accuracy

    99.97%

    Validated across 85,000+ monitoring locations.[5]
    Multi-signal cross-correlation: every FFT, GMF, cepstrum,
    RPM and temperature trace combined. Confidence builds as
    evidence agrees.

    03

    Prescriptions Acted Upon

    Up to 99%

    Your team acts because the prescription specifies which
    bearing, which gear, which shift—with the FFT evidence
    to justify it. Not an alert. A directive.

    04

    User-Validated Outcomes

    100%

    You confirm. The DRS report closes with before/after proof.
    Every validated outcome sharpens the next prescription.

    946[5]
    Plants online globally
    30+ countries · heavy industry
    157,115[5]
    Downtime hours eliminated
    Last 24 months · user-validated
    3.3B+[5]
    Data points trained on
    Sharpens with every closed work order
    99.97%[5]
    Equipment uptime
    Achieved on contract

    What success looks like: from reactive firefighting to prescribed reliability

    This is the shift that Crane AI Shield enables — from the world where your team responds to crane failures to the world where your team acts on prescriptions weeks before a failure occurs.

    Outcome Your world today (reactive) Your world with Crane AI Shield Verified improvement
    Unplanned breakdowns Failure-triggered response — you find out when the crane stops Prescriptions acted on 2–6 weeks before failure 8 of 10 eliminated[5]
    MTBF OEM intervals — not calibrated to your actual duty cycles Condition-based — intervene on signal, not schedule +25–30% MTBF improvement[6]
    Detection to response Hours to days — operator observation after failure Minutes — RPM-gated FFT + evidence trail delivered >80% reduction in response time[6]
    Emergency repair cost 3–5× premium — overtime, expedited parts, rigging Planned interventions replace emergency mobilisation Significant cost reduction[2]
    Safety compliance Manual logs, periodic inspections Continuous digital logging — audit-ready 100% interlock event visibility[5]

    Getting started: 5 days to live monitoring

    Deployment is structured around your operation — not ours. Only one day of crane downtime required. Start with your highest-criticality crane. Validate the value on your equipment. Scale at your pace.
    Day 1
    Mount sensors, route cabling, cut over to PlantOS™.
    Commissioning sign-off on site. Only day requiring crane downtime.
    Days 2–3
    Dashboard configuration, signal validation, baseline calibration.
    AI calibrated to the crane’s kinematic profile—gear-mesh and
    shaft-order frequencies mapped. Crane operates normally.
    Days 4–5
    Go-live: final validation, user training, system handover.
    First diagnostic typically within 30 days. 60-day evaluation
    period — 75% of payment due only on satisfaction.

    You already know how to run the plant.
    Now your sensors can keep up with you.
    845+ plants · 30+ countries · 111,600+ hours of unplanned downtime eliminated.
    Not from dashboards. From prescriptions. Validated by the operators who signed off.
    What is your crane not telling you?

    Try PlantOS™ today
    → infinite-uptime.com/contact

    Frequently Asked Questions


    What is wrong with standard battery PdM sensors on cranes?

    Standard battery PdM sensors fail cranes in three specific ways: they sample vibration only a few times per day, missing faults that develop between snapshots; they stop recording when the crane is under load — exactly when fault signatures are strongest; and their battery enclosures degrade rapidly under foundry heat, dust, and vibration. Crane AI Shield eliminates all three: RPM-gated FFT fires only under stable load conditions, sensors stream RPM and temperature 24/7, and IP68 SS316 hardware with 180°C-rated cabling is designed to survive where battery units fail.


    What makes RPM-gated FFT better than time-sampled vibration monitoring?

    Time-sampled monitoring captures vibration on a clock schedule — not when the crane is actually working. Accel and decel noise contaminates the spectrum, making it difficult to isolate genuine fault frequencies. RPM-gated FFT triggers only when the motor is in a stable speed band under load — producing clean spectra at the exact moment fault signatures are most distinguishable. This eliminates false alarms, reduces filtering requirements, and catches faults that time-sampled systems structurally cannot detect.


    What types of failures can Crane AI Shield detect, and how early?

    Crane AI Shield monitors up to 19 failure modes across the main hoist drive train: bearing defects (BPFO/BPFI/BSF), gear-mesh faults (GMF), gear tooth wear, gear backlash, shaft misalignment, coupling faults, rotor bar cracks, unbalance, structural looseness, and more. The Comprehensive tier adds long-travel wheel bearing defects. Vibration analysis using FFT fault frequency mapping identifies bearing and gearbox degradation 2–6 weeks before catastrophic failure. The Tata Steel Colors case study: Main Hoist Motor #3 flagged 12 days before likely failure — 10 hours of unplanned downtime avoided.


    How long does deployment take and what is the expected ROI?

    Deployment follows a structured 5-day plan with only one day of crane downtime required for sensor mounting and commissioning sign-off. AI calibration to the crane’s kinematic profile — mapping gear-mesh and shaft-order frequencies — is completed within Days 2–3. The system delivers a first diagnostic typically within 30 days, with a 60-day evaluation period and 75% of payment due only on satisfaction. ROI payback is typically achieved within 6–12 months: the Standard subscription is $24K per crane per year versus $75K–$250K+ per avoided main-hoist failure — a 3–10× return on the first catch.


    Can PlantOS™ scale from a single pilot crane to an entire fleet?

    Yes. Start with your highest-criticality crane, validate the outcome on your specific equipment, then scale at your own pace. The Fleet Operations Center provides a unified view of 100+ cranes — every crane needing attention ranked by fault progression, with preventable downtime hours tracked live. Infinite Uptime currently operates across 845+ plants in 30+ countries. Sensor placement scales with crane size; the scope of fault coverage does not change.

    References

    [1] Mazzella Companies — “Depending on the facility and its output, downtime can cost anywhere from $10,000 to $20,000 per hour for standard operations. High-production environments may lose hundreds of thousands of dollars per hour.” mazzellacompanies.com/learning-center/the-true-cost-of-overhead-crane-breakdowns/ (2026)

    [2] U.S. Department of Energy, as cited in OxMaint and eWorkOrders — Reactive maintenance costs 3–5 times more than planned preventive maintenance when all costs are included: emergency labour, expedited parts, production loss, cascading damage. oxmaint.com/blog/post/maintenance-cost-reduction-20-proven-strategies

    [3] Infinite Uptime ROI Estimate 2026 — “Standard at $24K / crane / yr vs $75K–$250K+ per avoided failure → 3–10× return. Payback on the first catch.” Across Infinite Uptime install base. infinite-uptime.com

    [4] iFactory / OxMaint — Vibration analysis using FFT fault frequency mapping can identify bearing and gearbox degradation 2–6 weeks before catastrophic failure. ifactory.jrsinnovation.com/blog/vibration-sensors-predictive-maintenance

    [5] Infinite Uptime PlantOS™ — Live data as of June 2026: 845+ plants, 30+ countries, 111,600+ hours downtime eliminated (last 24 months), 3.3B+ data points, 99.97% equipment uptime achieved on contract. infinite-uptime.com

    [6] Industry benchmark — Predictive maintenance associated with +25–30% MTBF improvement and >80% reduction in detection-to-response time. R. Keith Mobley, Plant Engineer’s Handbook, as cited in PDS Balancing (2026). Actual improvement varies by asset mix and programme maturity.
  • Your Crane Doesn’t Fail on a Schedule. So Why Is It Monitored on One?

    Your Crane Doesn’t Fail on a Schedule. So Why Is It Monitored on One?

    Your Crane Doesn’t Fail on a Schedule.
    So Why Is It Monitored on One?

    Standard predictive maintenance was built for steady-state machines. A duty-cycle crane behaves nothing like one, and that mismatch is exactly where the failures hide.

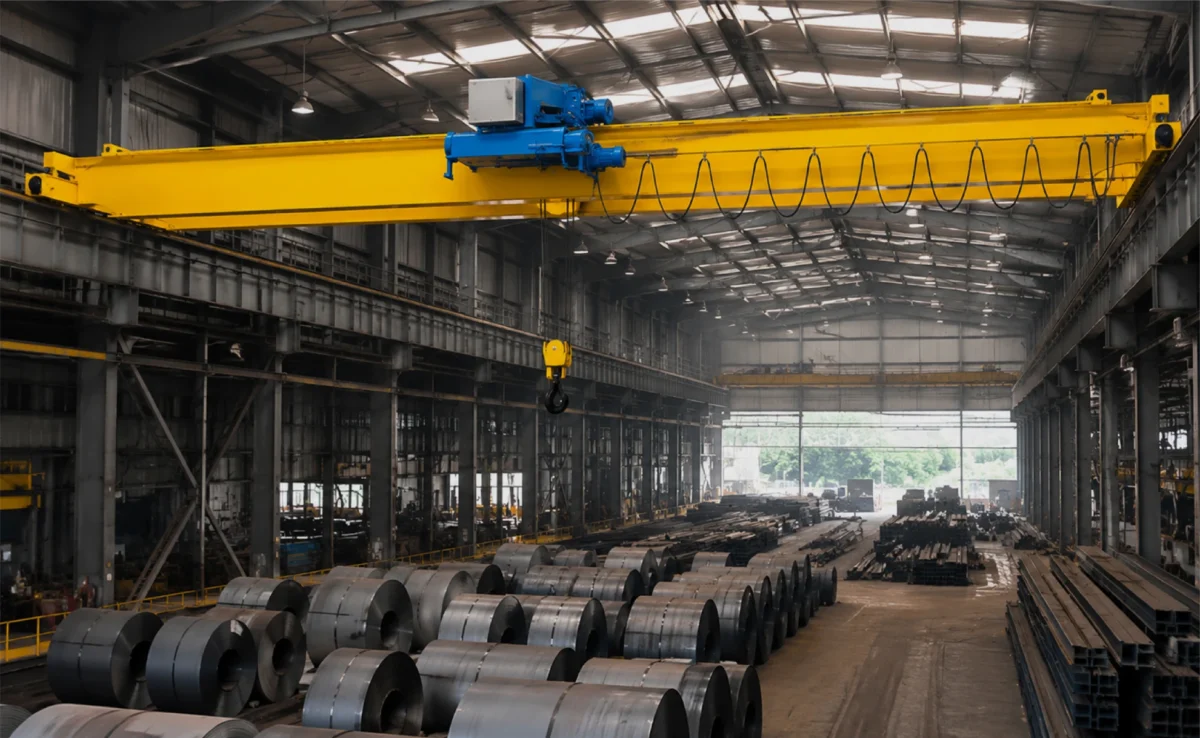
    Read Time: 8–9 minutes | Author – Chaiitanya Bulusu 3D rendering of a double girder overhead EOT crane with an electric wire rope hoist and the text: "Overhead EOT crane lifting a ladle in a steel melt shop, monitored by Crane AI Shield."

    The Short Version

    A crane is the most consequential moving asset on your floor, and it’s often the one your monitoring system understands least. Battery-sampled predictive maintenance (PdM) sleeps through the moments that matter, goes quiet under load, and degrades in foundry heat.

    Crane AI Shield watches the crane the way a crane actually behaves—always-on, RPM-aware, and engineered for the floor—then hands your operator a prescription, not another alert to chase. The system boasts a 99.97% prediction accuracy across 946 plants in 26 countries.

    What Actually Fails on a Crane

    You are the reliability manager. When the main hoist on the melt-shop crane drifts toward a seizure at 2 AM, you are the one who gets the call. A failed hoist doesn’t just idle one machine; it idles the entire bay.


    The failures Crane AI Shield is built to stop fall into recognizable patterns:

    • Surprise breakdowns: Bearings, gears, and rotating components letting go mid-shift, mid-load, with no warning.
    • Silent capacity loss: Slow degradation that quietly eats into uptime and throughput.
    • Repeat failures: The same fault returning on hard-to-reach wheels, gearboxes, and hoists.
    • The Cascade: A small $5,000 bearing fault that takes the gearbox, motor, and shaft with it, turning into a $500,000 incident.

    Every one of these is catchable early—but only if something is actually watching at the moment the fault first shows itself.

    A Crane is Not a Pump

    Most predictive maintenance tooling was designed to watch steady-state rotating equipment—motors and pumps that turn at a constant speed, in a fixed spot, all day. A crane breaks every one of those assumptions by accelerating, decelerating, sitting idle, and lifting under shock load.


    Drop battery-sampled PdM onto that asset and three structural gaps open up:

    • It wakes only a few times a day. Faults surface between samples and are never recorded.
    • It goes quiet exactly when it matters. Many systems stop reading the moment the asset is working, which is precisely when a fault under load reveals itself.
    • It dies before it can warn you. Sealed battery units degrade under sustained heat, dust, and vibration.

    What “Built for Cranes” Actually Means

    Crane AI Shield closes these gaps by changing how it watches:

    • It listens at the right moment. RPM is tracked live, and vibration is captured only when the crane is at a stable speed. This RPM-gated capture keeps noise out of the spectrum, meaning clean diagnostics and effectively zero false alarms.
    • It never sleeps. RPM and temperature stream 24/7, leaving no sampling gap for a fault to slip through.
    • It survives the floor. IP68 SS316 sensors with 180°C-rated cabling are engineered to keep working where battery units burn out.

    R P M   O V E R   T I M E

    Sharp zigzag RPM line across three phases.

    ↓  FFT vibration capture fires only inside the stable band

    Why One Signal is Never Enough

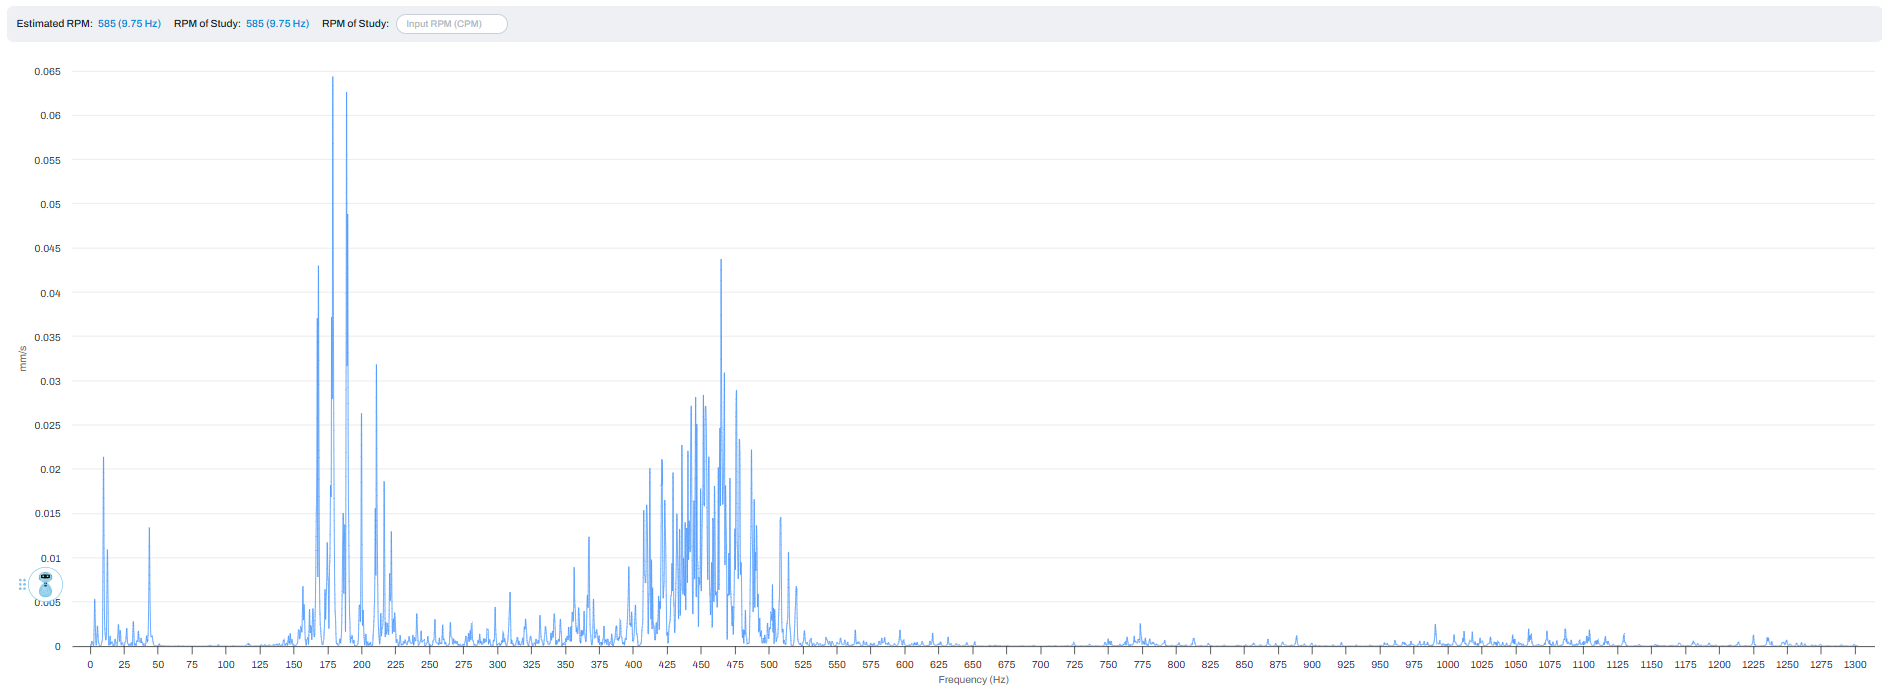
    An early-stage crane fault rarely announces itself on a single chart. Crane AI Shield continuously reads and cross-correlates gear-mesh frequencies, sidebands, cepstrum, time waveform, shockwave and envelope, PSD, RPM, temperature, and velocity. Confidence builds only as the evidence agrees, validated by a certified analyst before anything reaches your floor.


    FFT vibration analysis chart displaying vibration velocity (mm/s) versus frequency (Hz), with an estimated RPM of 585 (9.75 Hz) and prominent peaks around 180 Hz and 465 Hz.

    Multiple vibration-analysis traces cross-correlated into a single confirmed-fault diagnosis.

    From Alert to Closed Loop

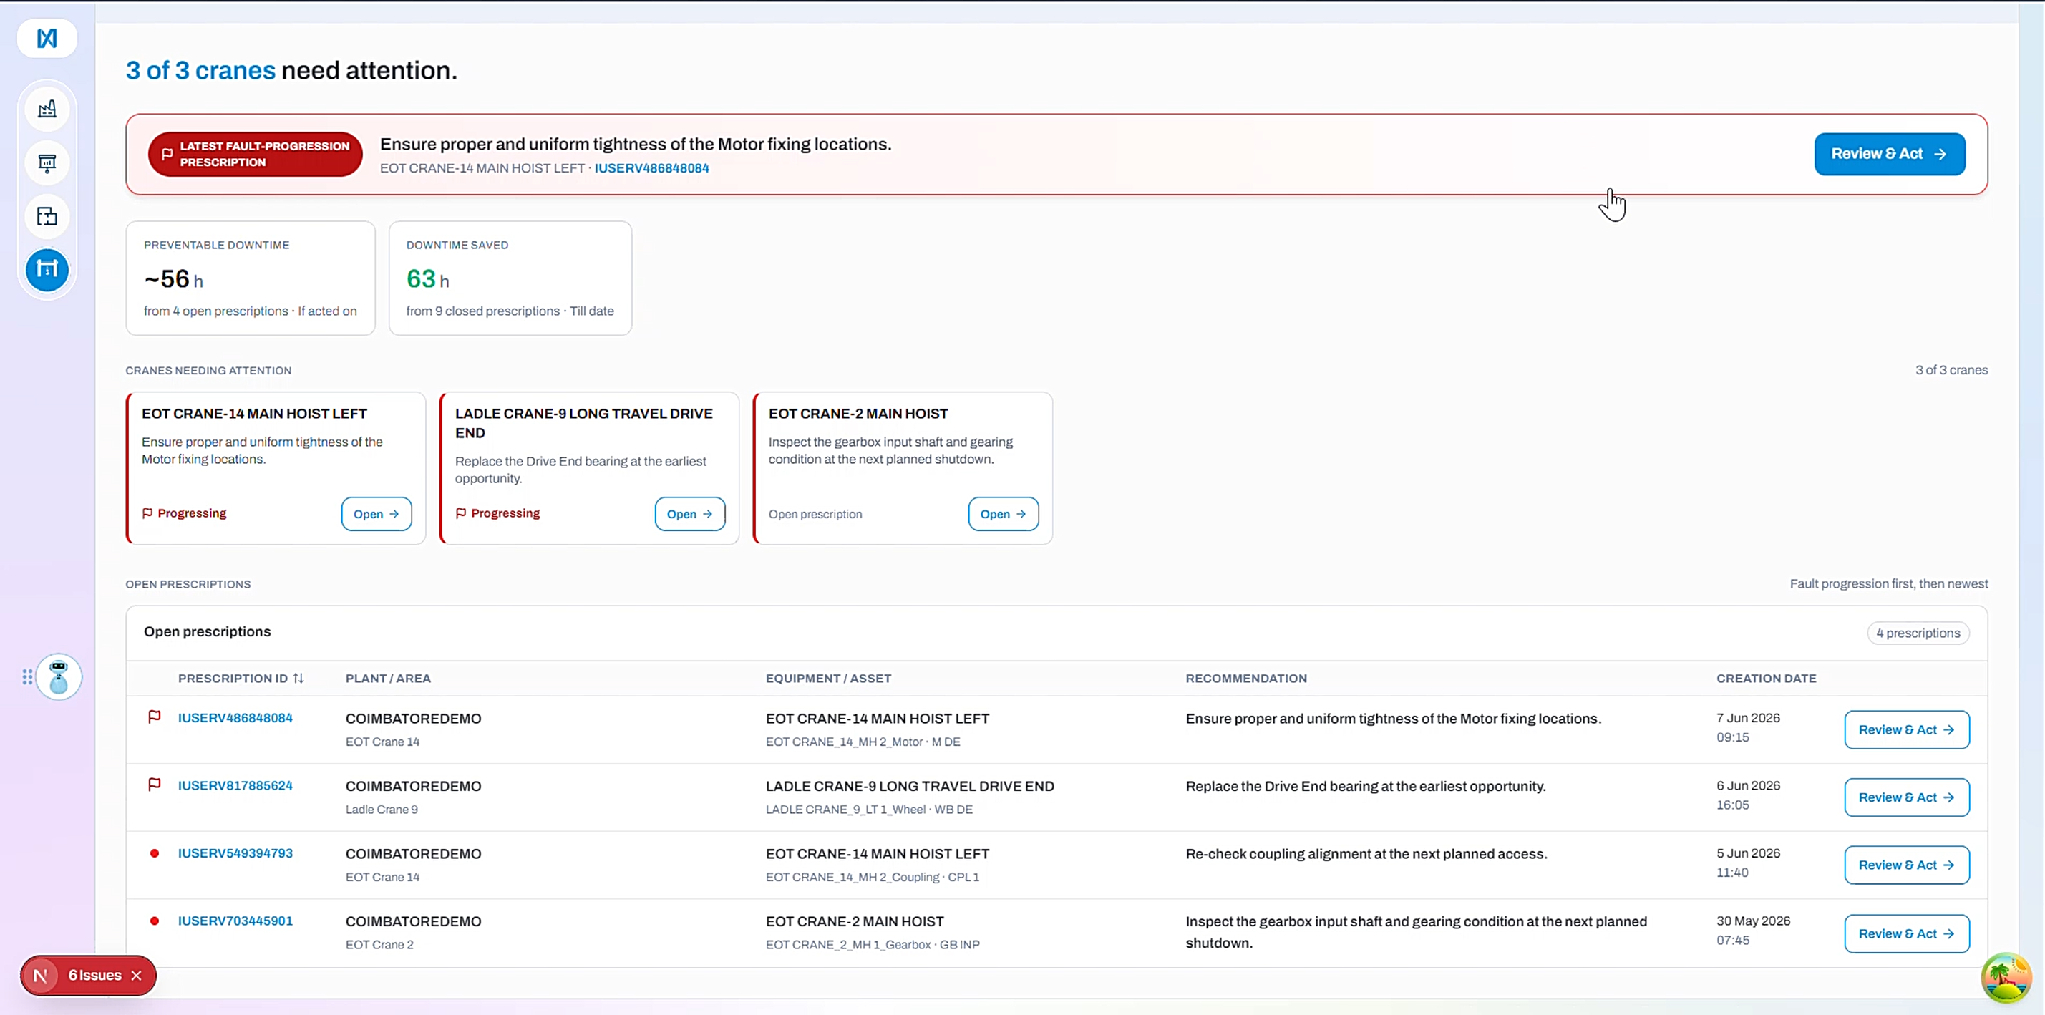
    The output isn’t a dashboard to decode; it’s a decision. This is the 99% Trust Loop on the floor:

    1. Contextualize: Every duty-cycle crane is ranked by fault progression.
    2. Predict & Prescribe: The screen reads the fix in plain words (e.g., “correct the hoist drive coupling alignment”).
    3. Validate: The operator marks the action done and confirms the accurate prediction.
    4. Loop Closed: The alert turns green, and confirmed outcomes feed back into the model.


    Industrial crane predictive maintenance dashboard displaying three cranes needing attention, maintenance recommendations, downtime metrics, and a list of open prescriptions.

    The 99% Trust Loop UI – Contextualize → Predict & Prescribe → Validate → Loop closed.

    Proof, Not Promise

    A melt-shop EOT crane at leading steel producing company runs 300-400 lift cycles a shift. When its main hoist motor bearing began drifting toward looseness, Crane AI Shield read the rising signature early and prescribed the exact correction. The result was one planned stop, a re-lube done on schedule, and hours of unplanned downtime eliminated on the bay’s highest-consequence asset.


    BASELINE DEVELOPING CRITICAL POST-ACTION → RECOVERY Baseline ~43 m/s² 250 200 150 100 50 0 Total Acceleration (m/s²) 24 Nov 01 Dec 08 Dec 15 Dec 22 Dec 29 Dec 05 Jan 12 Jan 19 Jan Dec 16 • Prescription raised to stakeholders 232 m/s² ≈ 5× baseline Dec 28 • Action taken

    Two Systems, One Unified View

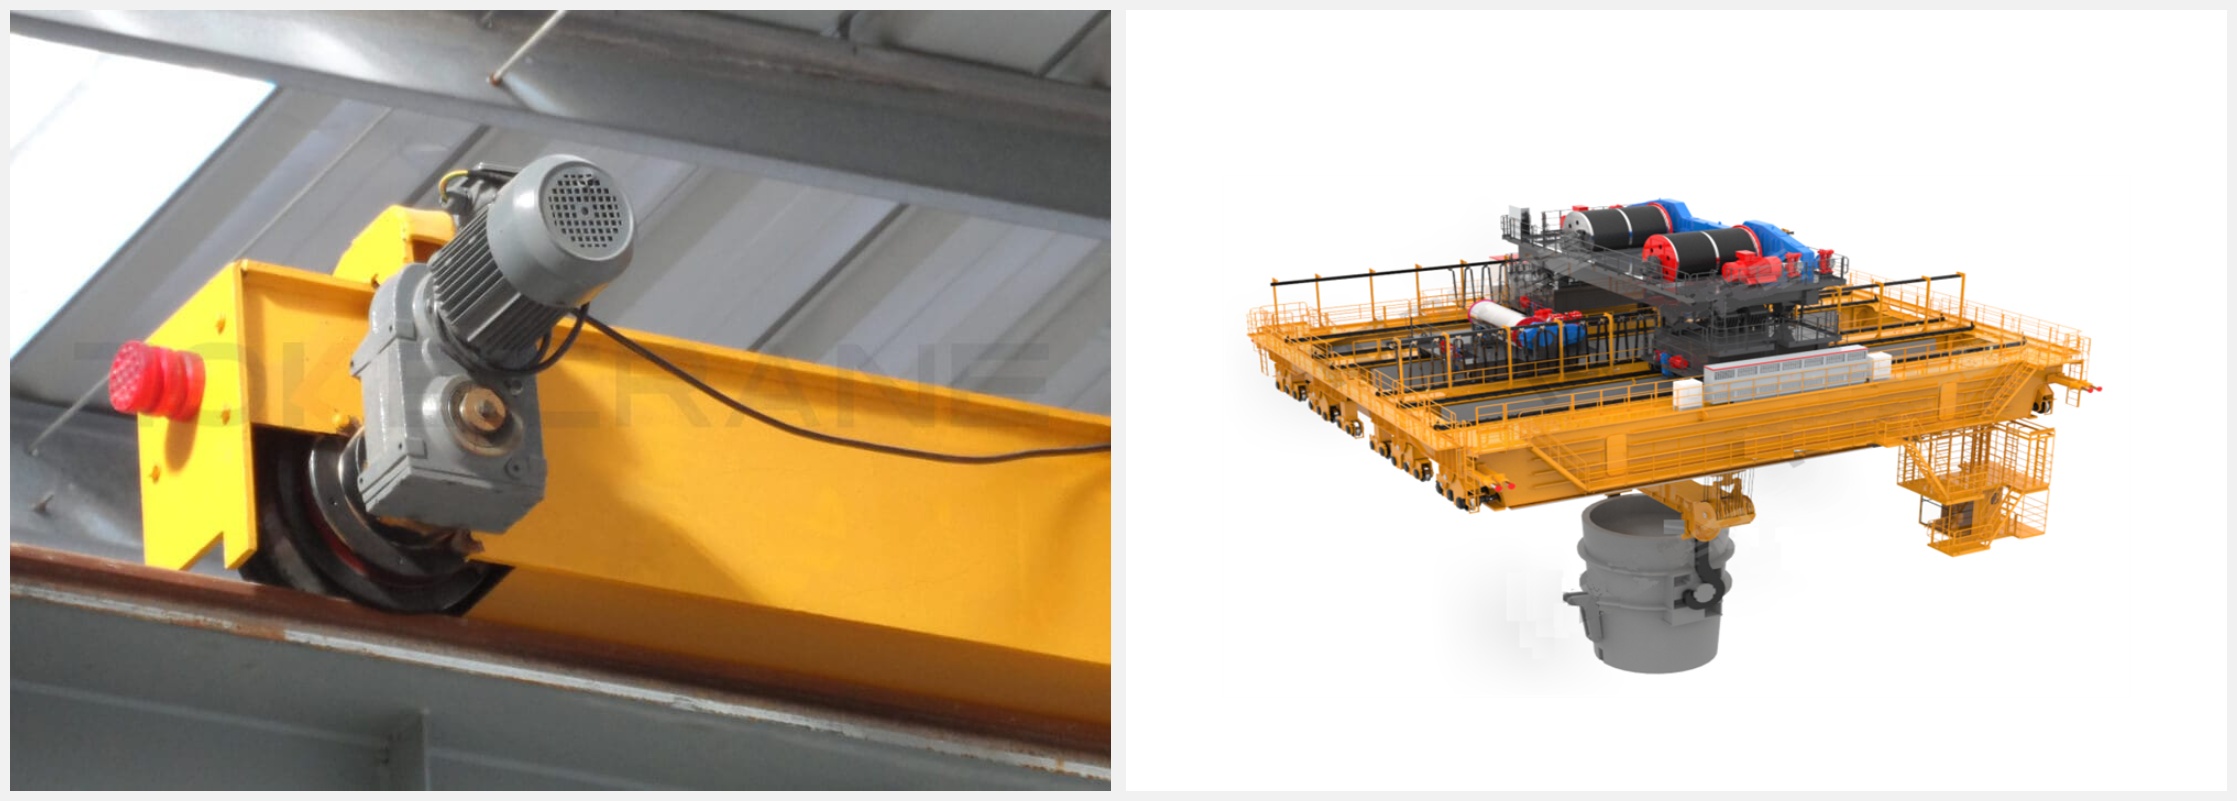
    Every EOT crane runs on two motor systems, and Crane AI Shield reads both:

    • The Main Hoist Drive: Monitored for gear-mesh defects, bearing degradation, and speed-correlated anomalies.
    • The Long-Travel System: Monitored for bearing defects, lubrication degradation, and wheel-side looseness.


    Split image showing a close-up of an overhead crane end carriage with a geared motor on the left and a 3D model of an offshore platform crane on the right.

    The Bottom Line

    Crane AI Shield isn’t just a sensor and a model bolted together; hardware and AI are engineered as a single system. Deployments run on a predictable roughly eight-week timeline. You already know how to run the plant. Crane AI Shield gives you the part you couldn’t see before—the fault building right now while every chart still looks normal.


    Watch a crane the way a crane behaves, or you’re not managing reliability. You’re hoping.


    Try PlantOS™ Crane AI shield today: https://iu.webstaging.in/contact

    Frequently Asked Questions


    1. What is wrong with standard battery PdM sensors on cranes?

    Standard battery PdM sensors fail cranes in three specific ways: they sample vibration only a few times per day, missing faults that develop between snapshots; they stop recording when the crane is under load — exactly when fault signatures are strongest; and their battery enclosures degrade rapidly under foundry heat, dust, and vibration. Crane AI Shield eliminates all three: RPM-gated FFT fires only under stable load conditions, sensors stream RPM and temperature 24/7, and IP68 SS316 hardware with 180°C-rated cabling is designed to survive where battery units fail.


    2. What makes RPM-gated FFT better than time-sampled vibration monitoring?

    Time-sampled monitoring captures vibration on a clock schedule — not when the crane is actually working. Accel and decel noise contaminates the spectrum, making it difficult to isolate genuine fault frequencies. RPM-gated FFT triggers only when the motor is in a stable speed band under load — producing clean spectra at the exact moment fault signatures are most distinguishable. This eliminates false alarms, reduces filtering requirements, and catches faults that time-sampled systems structurally cannot detect.


    3. What types of failures can Crane AI Shield detect, and how early?

    Crane AI Shield monitors up to 19 failure modes across the main hoist drive train: bearing defects (BPFO/BPFI/BSF), gear-mesh faults (GMF), gear tooth wear, gear backlash, shaft misalignment, coupling faults, rotor bar cracks, unbalance, structural looseness, and more. The Comprehensive tier adds long-travel wheel bearing defects. Vibration analysis using FFT fault frequency mapping identifies bearing and gearbox degradation 2–6 weeks before catastrophic failure. The Tata Steel Colors case study: Main Hoist Motor #3 flagged 12 days before likely failure — 10 hours of unplanned downtime avoided.


    4. How long does deployment take and what is the expected ROI?

    Deployment follows a structured 5-day plan with only one day of crane downtime required for sensor mounting and commissioning sign-off. AI calibration to the crane’s kinematic profile — mapping gear-mesh and shaft-order frequencies — is completed within Days 2–3. The system delivers a first diagnostic typically within 30 days, with a 60-day evaluation period and 75% of payment due only on satisfaction. ROI payback is typically achieved within 6–12 months: the Standard subscription is $24K per crane per year versus $75K–$250K+ per avoided main-hoist failure — a 3–10× return on the first catch.


    5. Can PlantOS™ scale from a single pilot crane to an entire fleet?

    Yes. Start with your highest-criticality crane, validate the outcome on your specific equipment, then scale at your own pace. The Fleet Operations Center provides a unified view of 100+ cranes — every crane needing attention ranked by fault progression, with preventable downtime hours tracked live. Infinite Uptime currently operates across 845+ plants in 30+ countries. Sensor placement scales with crane size; the scope of fault coverage does not change.

  • Why Your Mining Plant Keeps Breaking Down — And Why Your AI Can’t See It Coming

    Why Your Mining Plant Keeps Breaking Down — And Why Your AI Can’t See It Coming

    Why Your Mining Plant Keeps Breaking Down
    — And Why Your AI Can’t See It Coming

    Read Time: 8–9 minutes | Author – Kalyan Meduri

    Why Mining Plants Keep Breaking Down | Prescriptive AI Guide

    Somewhere right now, a crusher is about to fail.


    The maintenance team doesn’t know it yet. The vibration sensor on the bearing isn’t alarming. The DCS isn’t flagging anything. Everything looks normal — until it doesn’t, and a $40,000-per-hour production halt begins while the team scrambles to understand what happened, source emergency parts, and restart a comminution circuit that’s now backed ore up across the entire plant.

    This is not a technology failure. It is an architecture failure. And it plays out every day in open-pit mines, underground operations, and mineral processing plants across the world.


    The solution is not more sensors. It is not louder alarms. It is not even better predictive maintenance in the traditional sense.


    It is Prescriptive Vertical-AI for Outcomes — AI trained specifically on mining’s failure physics, correlating mechanical degradation and process-induced stress simultaneously, and prescribing specific action before the failure cascade begins.

    This is what Infinite Uptime built PlantOS™ to do. And this is why it works when generic AI doesn’t.

    What Is Vertical AI for Outcomes?

    Vertical AI for Outcomes is industry-specific AI that understands both equipment behavior and process conditions, identifies root causes, prescribes corrective actions, and converts industrial data into measurable, operator-validated business outcomes.

    The Problem Generic AI Cannot Solve

    Mining is one of the most punishing operating environments on earth. Crushers process thousands of tonnes of abrasive rock per hour. Conveyors run kilometres across open terrain under constant variable loading. SAG mills grind continuously at the intersection of mechanical stress and process chemistry. Slurry pumps move abrasive, corrosive fluid through systems under enormous pressure.


    Every crusher stoppage halts the mine. Every conveyor trip risks millions.


    Generic AI platforms — the kind trained on broad industrial datasets — can detect that a bearing is degrading. They can tell you that vibration on a conveyor drive is trending upward. What they cannot tell you is why — and in mining, the why is everything. Because in a mine, the mechanical fault and the process condition that created it are almost never independent.


    Consider what actually happens when a primary crusher bearing begins to fail.


    The bearing might show early-stage spalling — a mechanical fault, clearly detectable through vibration frequency analysis. Standard AI sees it and generates an alert. But what standard AI doesn’t see is that three days earlier, the ore feed grade changed. Rock hardness jumped significantly above the crusher’s optimised design point. Feed rate wasn’t adjusted to compensate. The result: chronic impact overloading — a process-induced stress — compressed what would have been a 6-month degradation timeline into a 3-week collapse.


    By the time the vibration alarm fires, the window for a planned intervention has already closed.


    This is the core problem that Prescriptive Maintenance solves: detecting not just the mechanical symptom, but the process condition creating it — weeks before the alarm knows to sound.

    ROOT CAUSE OF MINING FAILURES (WHAT REALLY HAPPENS)
    Process Change (Ore hardness ↑ / Feed variation)
    ↓
    Process-Induced Stress (Overload, impact, imbalance)
    ↓
    Accelerated Degradation (Bearing wear, spalling starts)
    ↓
    Mechanical Failure (Crusher breakdown / Conveyor failure)
    ↓
    Production Impact ($40K/hr loss, stoppage)
    ✖
    What Generic AI Sees: Mechanical Failure
    ✅
    What PlantOS™ Sees: Entire Chain (Process → Failure)

    Two Threats. One Asset. One Platform.

    At Infinite Uptime, we describe mining equipment reliability through a framework of two simultaneous threats attacking every critical asset:

    Threat 1 — Equipment-Borne Mechanical Faults01

     These are the faults that originate inside the machine: bearing wear, gear-mesh defects, misalignment, looseness, imbalance, cavitation, lubrication breakdown. They develop progressively and are detectable through spectrum analysis, envelope detection, and bearing frequency analytics. PlantOS™ covers 20+ specific mechanical failure modes across every category of mining equipment — from SAG mill pinion bearings to conveyor idler rollers to dragline swing motors.

    Threat 2 — Process-Induced Faults02

    These are the conditions that originate outside the machine, in the operating environment, and attack the equipment from the outside in. In mining, these include:

    • Crusher feed overloading from hardness variation or uncontrolled feed rates — creating impact loads on jaw plates and bearings that exceed design limits, causing accelerated spalling
    • Conveyor belt mistracking driven by off-centre loading at transfer points — initiating idler bearing seizure through asymmetric radial stress
    • SAG mill feed imbalance — where charge level variation creates cyclic overload on trunnion bearings and shell liners simultaneously
    • Slurry pump cavitation from process density excursions — creating pressure wave damage to impeller and seal assemblies
    • Vibrating screen deck overload from upstream feed surges — driving bearing preload beyond rated capacity
    • Hydraulic system contamination in excavator boom arms — accelerating pump and motor wear through abrasive particle ingestion

    TWO THREATS. ONE ASSET. [ CRITICAL MINING ASSET ]
    (Crusher / SAG / Conveyor)
    [Equipment-Borne Faults]
    (Inside the machine)

    • Bearing wear
    • Misalignment
    • Gear defects
    • Lubrication failure

    [Process-Induced Faults]
    (Outside the machine)

    • Feed Overloading
    • Ore hardness variation
    • Density fluctuation
    • Process imbalance

    ↓
    ↓ FAILURE CASCADE
    (Downtime + Cost + Loss)
    ✅
    PlantOS™ monitors BOTH simultaneously
    ✖
    Generic AI monitors ONLY one side

    Our prescriptive AI models, trained specifically for mining and metals, detect mechanical, electrical, and process-induced faults across every stage — from drilling, blasting, and hauling to comminution, beneficiation, and flotation.

    This is the critical differentiator of Prescriptive AI: because PlantOS™ is trained on mining-specific failure physics — not generic rotating equipment data — it understands the relationship between process parameters and mechanical degradation patterns that are unique to mining operations. It knows what a SAG mill trunnion bearing looks like when feed rate is correct versus when charge is running light. It knows the vibration signature of a crusher operating within specification versus one absorbing feed it wasn’t designed for.

    Generic AI has no idea. It has never seen a mine.

    What Prescriptive AI Looks Like in a Mine

    Predictive maintenance tells you something might fail. Prescriptive Maintenance tells you exactly what to do about it, when, and what happens if you don’t.

    In mining, this distinction is not academic. It is the difference between a controlled bearing replacement during a planned shutdown window and a catastrophic crusher failure that backs ore across the comminution circuit for six hours.

    Here is what a PlantOS™ prescription looks like in practice:

    Mechanical fault detected: Inner race defect — Jaw Crusher #3 Drive-End bearing. Velocity: 4.2 mm/s and rising. Pattern consistent with progressive spalling.

    Process correlation: Feed rate has been running 15% above rated capacity for the past 11 days. Impact load frequency consistent with feed grade excursion (hardness index +22% from baseline). Process-induced stress is accelerating mechanical degradation.

    Remaining Useful Life estimate: 18–22 days at current operating conditions. If feed rate is not adjusted, RUL compresses to 8–12 days.

    Prescription: (1) Reduce feed rate to rated capacity immediately — this extends RUL and prevents cascade to adjacent components. (2) Schedule bearing replacement within the next planned maintenance window (Day 14). (3) Order replacement bearing assembly — part number provided. (4) Inspect jaw plate for impact damage during replacement.

    What happens if you don’t act: At current degradation rate, bearing failure leads to shaft seizure. Secondary damage to gearbox estimated at $180,000 in parts. Production stoppage: 14–18 hours. Total financial impact: $2.1M–$2.8M.

    That is not an alert. That is a prescription — specific, actionable, financially quantified, and delivered weeks before the alarm knows to fire.

    PlantOS™ delivers 99.97% prediction accuracy with prescriptions digitally verified by domain experts before they reach your maintenance team for validation


    Predictive AI
    Detects Anomaly (“Bearing Degrading”)
    Provides Alert
    Requires Interpretation
    Reaction based
    Limited Impact

    Prescriptive AI
    Identifies root cause (Mechanical + Process)
    Provides exact action plan
    No Interpretation required
    Outcome driven
    Operator-validated outcomes

    ❌ Stops at detection
    ✅ Drives production decision

    The 99% Trust Loop™ — Why Mining Teams Actually Act on It

    There is a graveyard of AI systems in heavy industry that generated excellent predictions that nobody acted on. Alert fatigue, distrust of black-box outputs, and prescriptions that didn’t fit the operational reality of the plant all contributed.


    Infinite Uptime designed around this problem from the start through what we call the 99% Trust Loop™.


    Every prescription generated by PlantOS™’s Prescriptive AI models passes through 24/7 review by domain experts — reliability engineers with deep knowledge of mining equipment failure physics. They validate the prescription for contextual accuracy: is this recommendation appropriate for this specific asset, at this operating condition, in this part of the process? Only then does it reach the maintenance team.


    The result is not just high prediction accuracy. It is high prescription adoption — because the maintenance team trusts what they receive. They have seen it proven correct, repeatedly, and they know a human expert stands behind every recommendation.


    At Vedanta Group — one of the world’s largest producers of zinc, aluminium, copper, and iron ore — PlantOS™ achieved an 83.64%+ user-validation rate across 1,554 prescriptions, with maintenance teams actively choosing to act on PlantOS™ recommendations. At Hindustan Zinc alone, this translated to 5,039 hours of unplanned downtime eliminated and over $700,000 USD in production savings across mines and smelters. 


    These are not projections. They are operator-validated outcomes tracked through the PlantOS™ Digital Reporting System — signed off by the maintenance teams who acted on the prescriptions.

    The Energy Dimension: Why Reliability and Efficiency Are the Same Problem

    Mining operations are among the most energy-intensive on earth. Comminution alone — crushing and grinding — can account for up to 50% of a mine’s total energy consumption. 


    What most mining operators don’t realise is that mechanical degradation and energy inefficiency are the same problem viewed from different angles. A conveyor belt with idler misalignment doesn’t just fail — it overconsumes electricity for months before it does. A crusher operating with a worn liner doesn’t just produce substandard product — it draws excess power on every cycle. A slurry pump running in cavitation doesn’t just damage its impeller — it runs at 30% below rated efficiency while doing so.


    PlantOS™ detects these conditions simultaneously — the mechanical signature and the energy waste — and prescribes corrective action that addresses both. The result is not a choice between reliability investment and energy efficiency: it is a single prescription that delivers both.


    By prescribing corrective actions that address both reliability and energy efficiency simultaneously, PlantOS™ helps mining plants reduce energy cost per ton of ore processed while maintaining throughput stability. 

    Starting Where It Matters Most

    You don’t need to monitor everything to start getting outcomes. You need to start with the assets where a single failure creates the most operational and financial exposure.


    In a typical open-pit mining operation, that is usually: the primary crusher, the SAG/ball mill drives, the main overland conveyor, and the slurry pump station. These four asset categories account for the majority of unplanned downtime events — and the majority of recoverable cost.


    PlantOS™ deploys in weeks, integrates with existing historian, PLC, and DCS infrastructure, and delivers first prescriptions within days of go-live. The first prevented failure typically recovers the platform cost entirely.


    Most mining and metals plants start seeing measurable improvements in downtime reduction, equipment availability, and energy efficiency within 6–12 months.

    The Bottom Line

    Mining doesn’t have a data problem. It has a correlation problem.


    The faults that cause the most expensive shutdowns in mining don’t originate in one domain and stay there. They begin as process conditions — overloading, feed variation, abrasive excursions — that accelerate mechanical degradation until a bearing fails, a liner cracks, a pump impeller cavitates, and the production circuit stops.


    Generic AI sees the bearing. It doesn’t see the overloading that created it.

    Vertical AI for Outcomes — trained specifically on mining’s failure physics, correlating mechanical and process domains simultaneously, validated by domain experts, and delivered as actionable prescriptions — sees both. And it sees them weeks before the alarm.


    That is what Prescriptive Maintenance looks like when it’s built for mining. That is PlantOS Infinite Uptime’s PlantOS™ is the Prescriptive Vertical-AI for Heavy Manufacturing. Deployed across 946+ plants in 26 countries, PlantOS™ delivers Prescriptive Maintenance and AI for Outcomes across Mining & Metals, Steel, Cement, Chemicals, Tire, F&B, Pharma, and Energies.


    See what PlantOS™ can find in your mine:


    Explore the Mining & Metals solution:

    Frequently Asked Questions


    1. Why do mining plants still experience breakdowns despite having sensors and monitoring systems?

    Most plants already have sensors, but they operate in silos. Traditional systems detect mechanical faults but fail to correlate them with process conditions like overloading or feed variability. Without this correlation, the root cause remains invisible until it’s too late, leading to unexpected breakdowns.


    2. What is the difference between predictive maintenance and prescriptive maintenance?

    Predictive maintenance identifies that a failure might occur. Prescriptive AI goes further by recommending exactly what action to take, when to take it, and what the operational impact will be. This enables faster, more confident decision-making and prevents failure cascades.


    3. How does Vertical AI for Outcomes improve reliability in mining operations?

    Vertical AI for Outcomes is trained specifically on mining failure physics, allowing it to understand how process conditions and mechanical degradation interact. By correlating both domains, it detects issues earlier and delivers actionable recommendations that directly protect production outcomes.


    4. What are process-induced faults, and why are they critical in mining?

    Process-induced faults occur when operating conditions—such as overloading, material variability, or density changes—stress equipment beyond design limits. These faults are often the real cause behind mechanical failures, but most systems fail to detect them early.


    5. How quickly can PlantOS™ deliver value in a mining plant?

    PlantOS™ is typically deployed within weeks and begins delivering prescriptions shortly after installation. Many plants recover their investment with the first prevented failure, while measurable improvements in uptime, maintenance cost, and energy efficiency become visible within months.


    6. What kind of outcomes can mining companies expect from Prescriptive AI?

    By combining Prescriptive AI with Vertical AI for Outcomes, mining plants can achieve:

    • Reduced unplanned downtime
    • Higher equipment availability
    • Lower maintenance costs
    • Improved energy efficiency per ton processed
  • Online Asset Monitoring: The Definitive Guide to Turning Equipment Data into Verified Production Outcomes

    Online Asset Monitoring: The Definitive Guide to Turning Equipment Data into Verified Production Outcomes

    Online Asset Monitoring: The Definitive Guide to Turning Equipment Data into Verified Production Outcomes

    Read Time: 8–9 minutes | Author – Kalyan Meduri

    Online Asset Monitoring_

    What is Asset Monitoring?

    Asset monitoring is the continuous monitoring of industrial assets to ensure reliable operation, maximize equipment performance, and prevent unexpected failures.

    What Is Online Asset Monitoring?

    Online asset monitoring is the continuous, automated measurement of industrial equipment health using permanently installed sensors combined with advanced AI systems. Unlike traditional offline inspections, which depend on periodic manual readings, online monitoring creates a real-time, always-on view of asset behavior. It continuously captures vibration, temperature, and process data, transforming this information through Prescriptive AI into actionable recommendations rather than passive alerts. The objective is not just to observe equipment but to actively guide decisions that improve reliability and performance.

    Most industrial plants today have sensors streaming data 24/7. Vibration readings, thermal profiles, and motor current dashboards glow with it all. Yet breakdowns still happen, and unplanned downtime continues to cost billions. The reason is simple: data alone does not fix machines action does. The shift now underway in manufacturing is not about collecting more data, but about converting that data into clear, trusted, and timely actions. The plants leading in 2026 are not those with the most sensors, but those using AI for Outcomes to turn signals into decisions that protect production.


    Most platforms stop at prediction. Infinite Uptime takes it further. A prediction tells you that a bearing is degrading. A prescription tells you exactly which bearing to fix, when to fix it, what to order, and what production outcome to expect if you delay. This is the difference between insight and impact. Infinite Uptime operates as a Production Outcomes Partner for Heavy Industries, delivering measurable business results through PlantOS™ a Vertical AI for Outcomes platform. With deployments across 946 plant sites in 26 countries, PlantOS™ has delivered over 42,000 validated prescriptions, helping avoid more than 36,000 breakdowns and eliminate over 157,115 hours of downtime. These are not projections they are operator-validated outcomes.

    What Online Asset Monitoring Means in Heavy Industry

    In heavy industries such as steel, cement, mining, chemicals, and manufacturing, online asset monitoring goes beyond condition tracking. It becomes a core layer of operational intelligence that directly influences production outcomes. A modern system integrates multiple components into a unified framework. It begins with multi-modal sensors that capture high-frequency vibration, temperature, oil condition, and electrical signals. These are supported by edge intelligence devices that preprocess data at the source. The information then flows into integrated platforms that connect with existing systems such as SCADA, DCS, ERP, and CMMS, creating a unified operational view.


    At the analytics layer, AI models trained on industry-specific failure modes detect anomalies and estimate remaining useful life. However, the most critical layer is the prescriptive layer. This is where Prescriptive AI transforms detection into action, delivering ranked recommendations that operators can execute with confidence. When powered by Vertical AI for Outcomes, this architecture enables plants to move from monitoring assets to actively managing production performance.

    Is asset monitoring the same as equipment monitoring?

    No, they are not the same. Equipment monitoring tracks the condition of individual machines, whereas asset monitoring encompasses all critical plant assets to improve reliability, performance, and operational efficiency.

    Online vs. Offline Asset Monitoring: The Critical Differences

    Offline monitoring relies on periodic inspection routes, where technicians collect data manually using handheld devices. These inspections may occur monthly or quarterly, leaving significant gaps where failures can develop undetected. The quality of analysis depends heavily on individual expertise, and decisions are often delayed.


    Online monitoring eliminates these limitations by providing continuous, real-time visibility into asset health. Data is collected automatically, analyzed using AI models, and translated into actionable insights. Detection windows shrink from weeks to seconds. Diagnostic depth improves through multi-signal analysis rather than subjective interpretation. Most importantly, action shifts from reactive to proactive, with prescriptive recommendations replacing basic alerts. The result is a system that not only observes but actively contributes to operational performance.


    Capability Offline Asset Monitoring
    (Route-Based)
    Online Asset Monitoring (Continuous)
    Data Collection Periodic, manual inspection routes 24/7 automated sensor ingestion
    Failure Detection Window Days or weeks between readings Real-time anomaly detection
    Diagnostic Depth Analyst-dependent interpretation AI-driven, vertical-trained fault classification
    Work Order Integration Manual creation and scheduling Automated CMMS/ERP integration
    Data Storage Local files, spreadsheets, physical memory Secure, encrypted cloud architecture
    Low-Speed Asset Coverage Often impossible below 100 RPM Continuous monitoring from 2 RPM to 3,900 RPM
    Action Output Alert or trend report Prescriptive recommendation with ranked priority
    Outcome Tracking Manual follow-up, limited traceability Automated validation loop with audit-ready logs

    Why Prediction Alone Is No Longer Enough

    Most asset monitoring platforms today stop at prediction. They identify anomalies and generate alerts, but leave the interpretation and decision-making to plant teams. This creates a significant execution gap. Alerts without context lead to alarm fatigue. Trends without prioritization overwhelm teams already managing complex operations.


    To deliver real value, monitoring must evolve into decision support. It must answer not just what is happening, but why it matters and what should be done next. This is the role of Prescriptive AI. By correlating mechanical signals with process parameters such as pressure, temperature, throughput, and energy consumption, PlantOS™ creates context-aware insights. It identifies not only the presence of a fault, but its root cause and its impact on production. This transformation from prediction to prescription is what defines a true Vertical AI for Outcomes system.


    Industrial assets typically fail from two interconnected directions: equipment-borne faults and process-induced faults. Most platforms monitor only one of these domains. PlantOS™ monitors both simultaneously, because the interaction between them is where the most critical failures originate. For example, a rise in kiln drive current may not be an electrical issue it may indicate refractory degradation weeks before visible damage occurs. Only multi-domain intelligence can identify such patterns early.

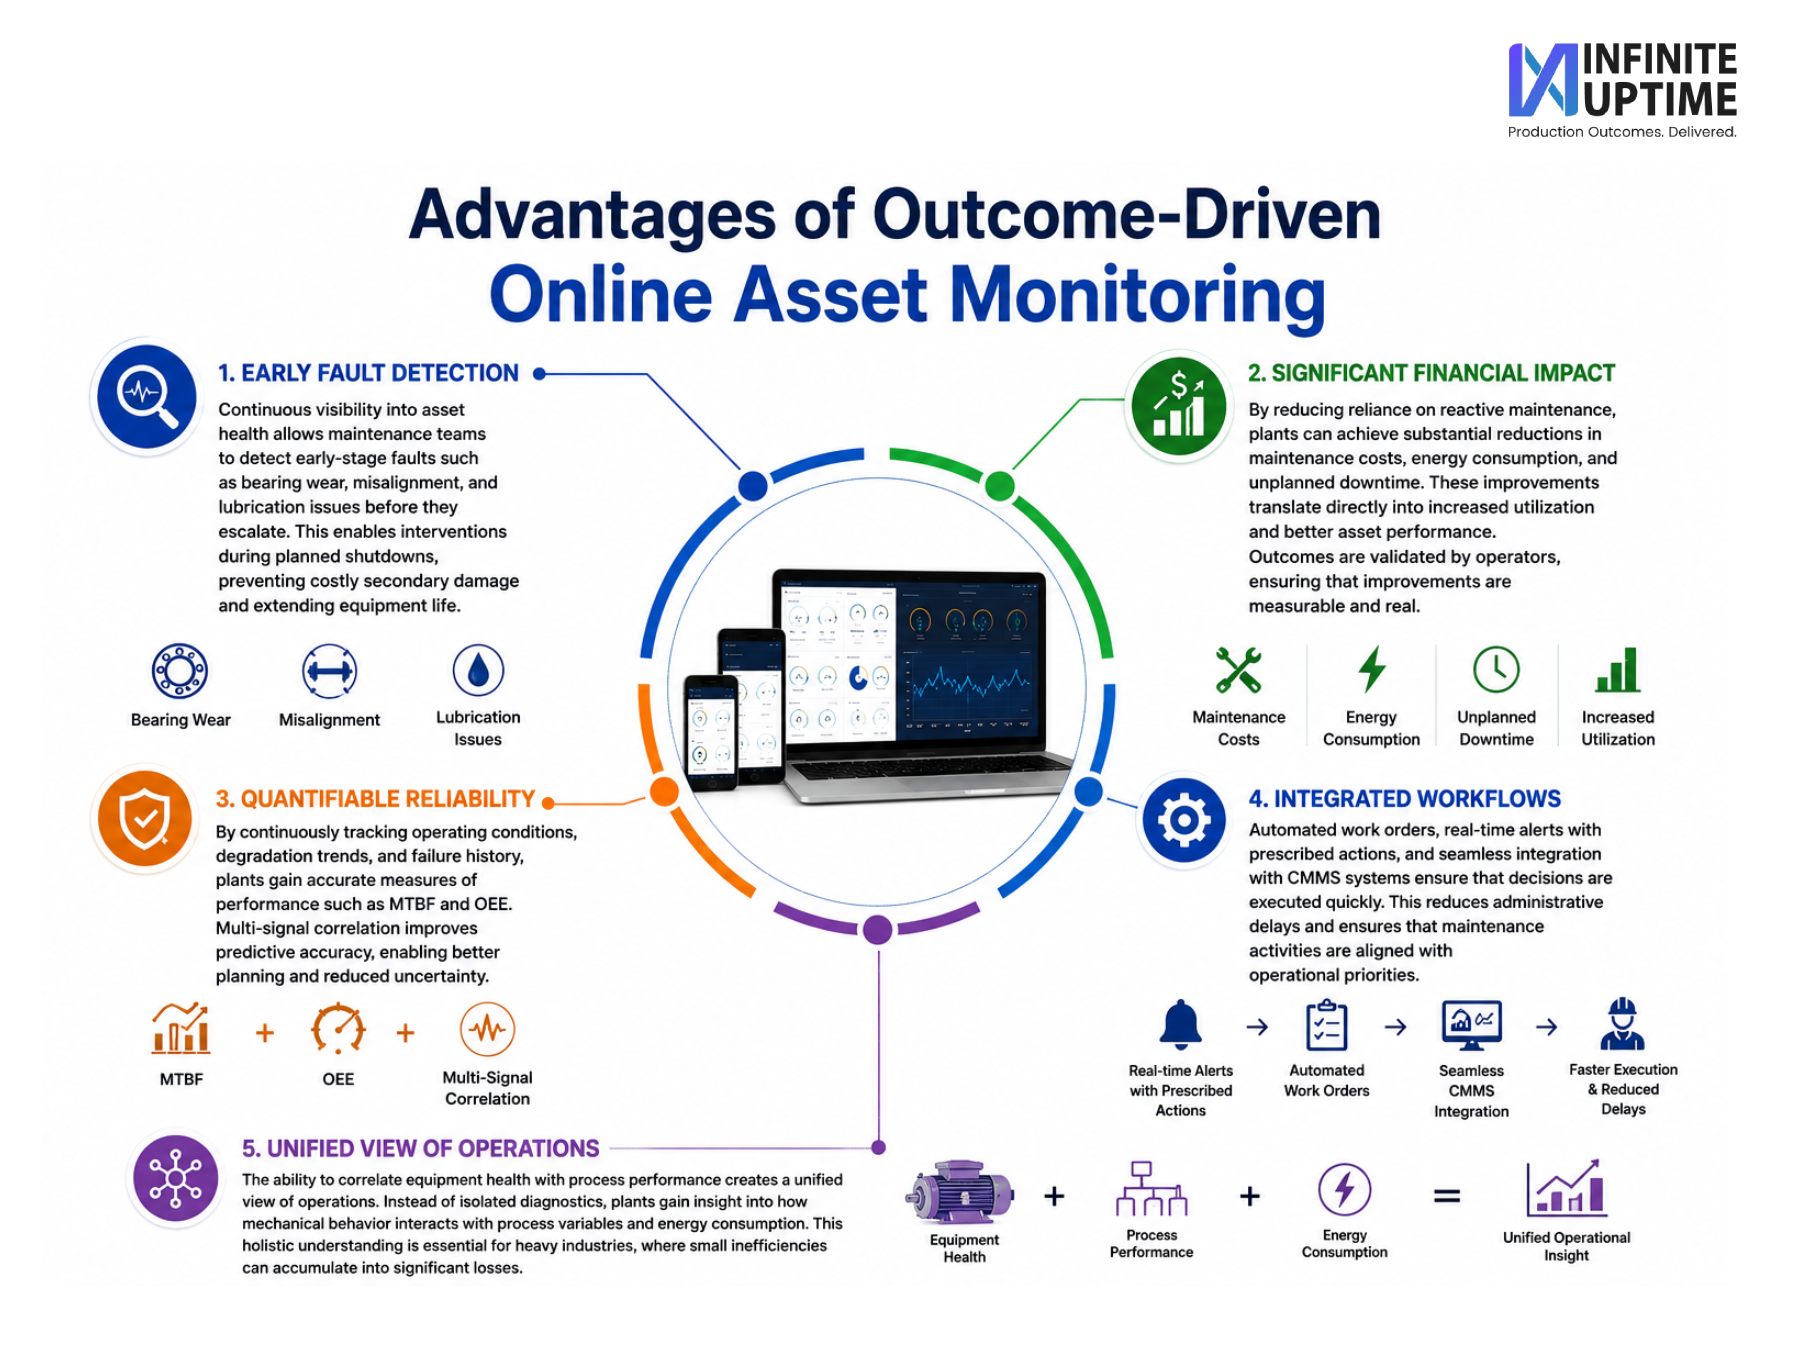
    Advantages of Outcome-Driven Online Asset Monitoring

    Advantages of Outcome-Driven Online Asset Monitoring

    Online asset monitoring delivers tangible benefits when it is outcome-driven rather than data-driven. Continuous visibility into asset health allows maintenance teams to detect early-stage faults such as bearing wear, misalignment, and lubrication issues before they escalate. This enables interventions during planned shutdowns, preventing costly secondary damage and extending equipment life.


    The financial impact is significant. By reducing reliance on reactive maintenance, plants can achieve substantial reductions in maintenance costs, energy consumption, and unplanned downtime. These improvements translate directly into increased utilization and better asset performance. What differentiates Infinite Uptime is that these outcomes are validated by operators, ensuring that improvements are measurable and real.


    Reliability also becomes quantifiable. By continuously tracking operating conditions, degradation trends, and failure history, plants gain accurate measures of performance such as MTBF and OEE. Multi-signal correlation improves predictive accuracy, enabling better planning and reduced uncertainty.


    Integration with maintenance workflows further enhances efficiency. Automated work orders, real-time alerts with prescribed actions, and seamless integration with CMMS systems ensure that decisions are executed quickly. This reduces administrative delays and ensures that maintenance activities are aligned with operational priorities.


    Finally, the ability to correlate equipment health with process performance creates a unified view of operations. Instead of isolated diagnostics, plants gain insight into how mechanical behavior interacts with process variables and energy consumption. This holistic understanding is essential for heavy industries, where small inefficiencies can accumulate into significant losses.

    Did You Know?

    Modern manufacturing plants generate millions of equipment data points every day, but the true value comes from converting those signals into actionable recommendations that prevent failures and improve production outcomes.

    Which Equipment Should Be Monitored Online?

    Not all equipment requires the same level of monitoring. Criticality analysis helps prioritize deployment. Critical assets that directly impact production or safety require continuous, multi-modal monitoring. Moderate-impact assets benefit from automated alerts, while low-impact assets may rely on periodic inspection.


    Special attention is required for low-speed equipment and harsh operating environments. Traditional monitoring systems often fail in such conditions, missing early defect signatures. PlantOS™ addresses this challenge through advanced sensing technologies combined with Prescriptive AI, ensuring comprehensive coverage across asset types.

    Technology Stack Behind Modern Monitoring

    A robust online monitoring system requires a full-stack architecture. At the sensing layer, specialized sensors operate across diverse environments, including extreme temperatures and hazardous zones. The data and AI layer includes secure cloud infrastructure, vertical-trained models, and advanced simulation capabilities that interpret complex industrial behavior.


    A critical differentiator is the human validation layer. AI-generated prescriptions are reviewed by domain experts, creating a trust loop that ensures accuracy and continuous improvement. This hybrid approach combines machine intelligence with human expertise, ensuring reliability in real-world conditions.


    At the delivery layer, insights are integrated into operational systems through APIs, dashboards, and automated workflows. Every prescription is tracked to its outcome, creating a closed-loop system where Prescriptive AI directly drives measurable results.

    Online Asset Monitoring Across Industries

    Industrial challenges are not uniform, and monitoring systems must reflect this reality. PlantOS™ applies Vertical AI for Outcomes across multiple sectors, adapting to industry-specific conditions. In steel plants, it correlates thermal and mechanical stresses to prevent critical failures. In cement, it identifies process drift that impacts energy efficiency. In mining, it enables remote monitoring of distributed assets. In food and beverage, it supports low-speed hygiene-critical equipment. In chemicals and pharmaceuticals, it ensures batch consistency and regulatory compliance.


    Across all industries, the objective is consistent: convert data into decisions that improve production outcomes.

    Conclusion

    Online asset monitoring is now a standard capability in modern manufacturing. The real differentiator lies in how effectively data is converted into action. Systems that stop at alerts create noise. Systems that deliver prescriptions create results.


    Infinite Uptime is redefining this space as a Production Outcomes Partner for Heavy Industries, using PlantOS™ a Vertical AI for Outcomes platform powered by Prescriptive AI to bridge the gap between detection and execution. By transforming raw data into operator-validated actions, PlantOS™ enables plants to achieve lower costs, higher throughput, and improved reliability.


    The future of industrial operations lies not in monitoring more, but in acting better. From data to decisions, from insights to outcomes this is the evolution that will define the next era of manufacturing.

    TERMINOLOGY GUIDE

    Asset Condition Monitoring, IoT Asset Monitoring, and Asset Health Monitoring: Are They the Same Thing?

    These four terms overlap heavily, but each carries a slightly different emphasis.

    Term

    What It Means

    Asset Condition Monitoring Refers to the practice of tracking specific condition indicators such as vibration, temperature, and oil quality on a piece of equipment. Online asset monitoring is asset condition monitoring performed continuously rather than periodically.
    Industrial Asset Monitoring Applies the same practice specifically within a manufacturing or heavy-industry setting, where the assets being monitored include production equipment such as kilns, cranes, mills, pumps, and motors.
    IoT Asset Monitoring Describes the technology layer that makes online monitoring possible at scale, using connected wired or wireless sensors to transmit data over networks such as cellular or Wi-Fi, without requiring a technician to be physically present.
    Asset Health Monitoring Describes the outcome of monitoring: a continuously updated view of how healthy—or how close to failure—a given asset is, usually expressed as a status, health score, or specific fault flag rather than raw sensor data.

    In short: IoT asset monitoring is the infrastructure, asset condition monitoring is the practice, industrial asset monitoring is the setting, asset health monitoring is the output, and online asset monitoring is the umbrella term that ties them together—continuous, connected, and real-time.

    Ready to Move from Data to Outcomes?
    If your plant is still operating on alerts, the next step is clear.


    Request a Production Outcomes Assessment and see how PlantOS™ Vertical AI for Outcomes—can transform your operations into measurable, sustained performance.
    Get in touch here →

    Read More on Industrial Energy Efficiency

    Frequently Asked Questions


    What is the difference between predictive and prescriptive maintenance?

    Predictive maintenance identifies potential failures. Prescriptive AI goes further by recommending specific actions, timelines, and expected outcomes, enabling faster and more accurate decisions.


    How long does PlantOS™ take to deploy?

    Most deployments are completed within 6–8 weeks, depending on plant size and asset coverage.


    Does PlantOS™ integrate with existing systems like SAP or CMMS?

    Yes, PlantOS™ integrates seamlessly with existing enterprise systems to automate workflows and improve maintenance efficiency.


    What kind of ROI can plants expect?

    Plants typically see rapid ROI through reduced downtime, lower maintenance costs, and improved throughput, driven by operator-validated outcomes.

  • True Cost of Process Instability in Chemical Plants

    True Cost of Process Instability in Chemical Plants

    When the Equipment Lies,the Process Pays:
    The True Cost of Process Instability in Chemical Plants

    Read Time: 8–9 minutes | Author – Kalyan Meduri

    See how equipment faults drive energy losses, process drift, and quality issues—and how AI helps detect and prevent them early.

    The dashboard says everything is fine. Steam is flowing. Temperatures are within range. The column is running. And yet — somewhere between the sensor and the spreadsheet — your plant is silently burning money.

    This is not a hypothetical. It is the operational reality for hundreds of chemical plants running today: equipment that degrades quietly, process parameters that drift slowly, and DCS systems that see none of it until the damage is already done.

    In chemical manufacturing, the relationship between equipment reliability and process stability is not indirect. It is not a soft correlation. It is a direct, measurable, cost-generating link — and most plants are managing the symptoms while the root cause keeps compounding.

    This blog makes that link explicit. With real industry figures, real examples, and the evidence for why prescriptive AI is the only tool that can break the cycle.

    The Invisible Thread: How Equipment State Drives Process Behaviour

    Every process engineer knows that distillation, separation, and reaction processes require stable inputs to deliver consistent outputs. What is less often acknowledged is that the primary source of process instability is not the process itself — it is the equipment running it.

    Consider the chain:

    •  A condenser fouls → heat transfer efficiency drops → steam demand rises to compensate → column pressure fluctuates → separation efficiency falls → product exits with higher impurity levels

    •  A steam trap fails → live steam bypasses the system → steam header pressure fluctuates → column base temperatures swing → residence time changes → unconverted intermediates accumulate in product

    •  A centrifugal pump impeller wears → flow rate drops below design → heat exchanger duty falls → outlet temperatures drift → reaction kinetics shift → yield and quality decline

    Process instability is rarely a process problem. It is an equipment problem that the process has been asked to absorb — and eventually, it cannot.

    This is the invisible thread: equipment degradation → process-induced fault → energy waste → quality loss → production risk. Each step is separated by time and distance on the plant floor, which is exactly why traditional monitoring systems miss it.

    REAL TIME EXAMPLE  |  ETHANOL REACTION COLUMN, SPECIALTY CHEMICALS

    At a specialty chemicals plant, an EA3 Kettle reaction column showed an SDS/Ethanol factor varying between 0.4 and 1.4 against a stable expected average. The column was running. Steam was flowing. But unconverted ethanol was accumulating in the product — run by run, shift by shift — with no alarm, no trip, and zero dashboard visibility.

    PlantOS™ ran a multi-parameter regression across 100+ runs and identified the root cause:
    condenser and cooling tower fouling reducing thermal efficiency, causing unsteady steam supply and outlet temperature instability

    No individual DCS alarm had fired. The fault was only visible by correlating six parameters simultaneously across time. After corrective cleaning and prescribed operating ranges, model accuracy improved from R² = 0.38 to R² = 0.77. Off-spec product: eliminated.

    The Energy You Are Paying For Twice

    Distillation alone accounts for approximately 40% of total energy consumption in chemical and refining plants. That is not a rounding error — that is the single largest energy end-use in most chemical facilities, and it is running under suboptimal conditions in most plants.


    When equipment degrades and process conditions drift, energy is consumed in two ways: once to do the intended work, and again to compensate for lost efficiency. This ‘double billing’ is the most underreported cost in chemical manufacturing.


    Where the Energy Goes — The Fouling Problem

    Heat exchanger fouling is one of the best-documented and least-addressed contributors to energy waste in the chemical sector. The data is stark:

    $20B+
    Annual global cost of heat exchanger fouling [2]
    0.25%
    Of GDP of all industrialised nations, every year [3]
    50%
    Of heat exchanger maintenance costs caused by fouling [4]
    22–38%
    Of purchased energy wasted per plant [5]

    The mechanism is straightforward: fouling creates a thermal resistance layer on heat transfer surfaces. The thicker the layer, the more energy the system consumes to achieve the same duty. Operators compensate by increasing steam flow — masking the underlying degradation while the energy bill climbs.

    Primary Energy Loss Contributors in Chemical Plants

    Estimated contribution to total avoidable energy loss per plant

    Steam system
    inefficiency
    35%
    Steam trap failures, distribution losses, uncontrolled blowdown

    Heat exchanger
    fouling
    28%
    Condenser, pre-heater and reboiler fouling reducing thermal duty

    Suboptimal column
    operation
    22%
    Pressure & temperature drift outside optimal separation window

    Pump/compressor
    degradation
    15%
    Wear-driven efficiency loss in critical rotating equipment
    Sources: iFactory Energy Optimization Platform (2026); Müller-Steinhagen & Malayeri (2010); IMPO Magazine; US DOE Chemical Bandwidth Study

    When Equipment Faults Become Product Quality Problems

    Product quality in chemical manufacturing is directly downstream of process stability — which is directly downstream of equipment state. The chain is mechanical, not probabilistic. And yet, most quality deviation analyses begin at the process level without ever reaching the equipment root cause.


    In distillation and separation processes, the pathway is well-established:

    1
    Equipment
    Degrades
    Fouled condenser,
    worn pump,
    failing steam trap
    2
    Process Drifts
    Pressure drop,
    temperature excursion,
    steam instability
    3
    Separation
    Fails
    Column cannot
    maintain efficiency
    window
    4
    Impurities
    Build
    Unconverted
    intermediates
    enter product stream
    5
    Quality
    Deviates
    Off-spec output,
    rework,
    batch rejection,
    customer impact

    The challenge is that quality deviations rarely present as a single dramatic event. They accumulate as gradual drift — a slowly worsening SDS factor, an increasing impurity trend, a creeping rework rate. By the time the quality team raises an alarm, the equipment cause is weeks old and the process has already absorbed the full cost.

    INDUSTRY DATA: THE QUALITY COST
    Unplanned downtime and off-spec production cost the chemical industry an estimated
    $20 billion annually.
    A single unplanned process upset in a large continuous chemical facility can cost
    $260,000 per hour
    in production losses alone, before accounting for waste disposal, rework, or customer penalties.

    REAL-WORLD PATTERN

    Compressor Valve Wear → Upstream Pressure Swing → Reactor Yield Loss

    In continuous chemical reactors, feed pressure stability is critical to maintaining residence time and, therefore, conversion rates. A worn compressor valve introduces pulsation into the feed stream. This creates micro-fluctuations in pressure that shift residence time by seconds per cycle — imperceptible in any single sample, but statistically significant across a shift.


    The result: a plant running at 96% conversion reports a gradual drift to 93%. Over a month, this represents hundreds of tonnes of product yield loss — attributable, on root cause analysis, to a $400 compressor valve that had been degrading for six weeks before the yield trend was investigated.


    The DCS showed no alarm. The process historian showed no trip. The quality dashboard showed a trend that was attributed to raw material variability — incorrectly — for three weeks.

    The Compound Effect: Why Small Variations Cost Big

    The costs of process instability are not additive — they are multiplicative. Energy waste, quality loss, and operational risk reinforce each other in a cycle that accelerates without intervention.

    Cost Impact Layers of Unaddressed Process Instability

    Relative contribution to total financial exposure per facility
    (illustrative, based on industry benchmarks)

    Energy
    overconsumption
    30%
    Excess steam, power and utilities drawn to compensate for degraded equipment

    Off-spec / rework /
    yield loss
    35%
    Quality deviations, batch rejections, downstream reprocessing cost

    Unplanned downtime
    25%
    Production loss, emergency maintenance, restart cost

    Accelerated
    equipment
    replacement
    10%
    MTBF reduction, premature wear, shortened asset life
    Sources: ARC Advisory Group; Aberdeen Group; McKinsey & Company Operations Practice; Infinite Uptime field data
    What makes this particularly costly is the time lag. A steam trap that begins bypassing in January may not manifest as a quality deviation until March and an unplanned shutdown in May. By the time cause and effect are connected — if they are connected at all — the plant has absorbed three months of compounding loss without understanding why.

    Why DCS Alarms and Energy Reports Miss What Actually Matters Why Traditional Monitoring
    Fails — and PlantOS™ Succeeds

    Chemical plants already have data. What they lack is contextual intelligence. DCS alarms monitor thresholds. Energy reports aggregate results. Quality systems log deviations. PlantOS™ works between them.

    • Detects anomalies early — before individual thresholds are breached
    • Correlates across process, energy, and equipment simultaneously
    • Prescribes operator-validated actions with timing, root cause, and business impact
    • Builds a living operational memory of what worked, where, and under which conditions

    This approach aligns with proven industrial AI research showing that multi-parameter, plant-scale anomaly detection dramatically outperforms static threshold alarms in process manufacturing environments. The EA3 Kettle case below is not a hypothetical. It is a direct demonstration: the column had DCS, SCADA, and operator rounds. None of it caught the six-parameter drift that PlantOS™ identified across 100+ production runs.

    ⚠️ Reactive Operations ✅ With Plant OS ™, Prescriptive AI
    Fault detected after product deviation Fault detected before process impact begins
    Single-tag alarms miss multi-parameter drift Cross-parameter correlation catches compound signatures
    Root cause found by exception (or not at all) Root cause identified and ranked by regression influence
    Operator intervenes reactively under pressure Prescription delivered with timing, action, and context
    Energy overconsumption continues for hours/days Operating ranges prescribed to prevent drift before it compounds
    Equipment replaced on schedule or at failure MTBF extended by operating within prescribed parameter bands

    The Gap That Remains — and Where It Lives

    Chemical plants are not data-poor. They are connection-poor. DCS platforms show what is happening in distillation columns, reactors, heat exchangers, steam systems, and utilities. Quality management systems explain why product deviates after it has already deviated. Energy and utility reports show what already occurred — after the batch is closed, the run is logged, and the bill is paid.


    This is the gap where energy cost, product quality, and reporting confidence accumulate quietly. It is where carbon exposure widens, sustainability data becomes indefensible, and corrective action becomes reactive instead of economic.


    Closing this gap requires more than dashboards or alarms. It requires continuous correlation between equipment health, process behaviour, and energy intensity — followed by prescriptive actions that operators can validate and trust. This is precisely where Infinite Uptime’s Process Business, built on PlantOS™, operates.

    PlantOS™ identifies energy-relevant anomalies in chemical operations while they are still recoverable:


    •  Distillation column pressure and temperature drift before rising steam rate hardens into sustained cost

    •  Reactor conversion inefficiency from feed instability before yield loss compounds across batches

    •  Heat exchanger fouling trajectory before thermal duty falls and column separation is compromised

    •  Steam trap failure before header pressure instability propagates to column base temperature

    •  Pump and compressor degradation before flow loss impacts heat exchanger duty and reactor feed stability

    Critically, the system does not act in isolation. Every recommendation is reviewed, validated, and owned by operators on the floor. This is not automation replacing judgment — it is agentic intelligence amplifying it. Over time, each validated intervention becomes part of a growing operational memory: what worked, under which operating conditions, on which assets — and with what measurable impact on energy, cost, and product quality per tonne.

    In the Field: What Operator-Validated Outcomes Look Like
    In a Chemical company,

    The EA3 reaction column showed significant variability in the SDS/Ethanol factor (ranging from 0.4 to 1.4), indicating unstable performance despite normal operation. Analysis revealed that this variation was driven by unsteady steam supply, pressure drops, and outlet temperature deviations, particularly during transient conditions like low feed and startup/shutdown. 

    PlantOS™ identified six key influencing parameters and prescribed optimal operating ranges to stabilize the process. The root cause was traced to reduced thermal efficiency from condenser and cooling system issues, leading to corrective actions including targeted cleaning of condensers and cooling towers to restore stable operation and prevent further efficiency losses.


    This is not just a case study prepared for a presentation. This is Process Prescription Report generated by PlantOS, acted & validated by plant operators, and time-stamped to the hour. The observation, diagnostic, recommendation, corrective action, and business impact are all in one record — auditable, explainable, and Reporting ready.


    PlantOS™ moves from raw plant data at the equipment and process layer through edge connectivity, platform execution, and prescriptive analytics, to decision planning, AI orchestration, and strategic governance. For chemical process management, the critical path runs through Process Canvas — which makes energy drift visible and explainable — and Process Prescript, which converts correlated anomalies into timed operator actions. The 3–8% energy reduction validated through this path is not a modelled estimate. It is an outcome confirmed by operators who acted on prescriptions, closed the loop, and logged the result.


    This is what positions PlantOS™ as Industrial Agentic AI for Operator-Validated Outcomes — not a monitoring layer, but a decision layer that closes the loop between data, human judgment, and measurable impact.

    “Process-induced faults inflate energy, carbon, and cost while production looks stable. PlantOS™ closes that blind spot — not by replacing operators, but by giving them actionable, trusted insight exactly where conventional systems go silent.”

    If you only see problems after the monthly quality or energy report, you’re already paying for them!


    Infinite Uptime’s PlantOS™ helps chemical manufacturing plants identify and correct energy-relevant process anomalies in real time — before they become quality deviations, carbon costs, or production losses. To explore what this looks like for your operations,

    Get in touch here →

    Frequently Asked Questions


    1. Is process instability really an equipment problem?

    Yes. In most cases, process instability originates from equipment issues like fouling, steam imbalance, or wear — which the process is forced to absorb until performance starts degrading.


    2. Why don’t DCS and SCADA systems catch these issues?

    Because they monitor individual parameters in isolation. Process inefficiencies are caused by multi-parameter interactions, which remain invisible unless correlations are analyzed together.


    3. How does process drift impact product quality?

    • Even small deviations in pressure, temperature, or flow can reduce separation efficiency or alter reaction conditions, leading to gradual buildup of impurities and off-spec output

    Read More Blogs

    References:

    • Kiss, A.A. & Smith, R. (2020). Rethinking energy use in distillation processes for a more sustainable chemical industry. Energy, 196, 117–143. ScienceDirect. Distillation accounts for ~40% of energy used in chemical and refining plants.
    • JLCPCB Technical Blog (2026). Knowing the Silent Crisis in Industrial Heat Exchangers. Estimates: $4.2B–$10B in the US annually; $20B+ globally in fouling-related costs.
    • Müller-Steinhagen, H. & Malayeri, M.R. (2010). Cost of heat exchanger fouling. Cited in HeatX Global Review. Total fouling cost estimated at 0.25% of GDP of industrialised countries.
    • IMPO Magazine. Fouling in Heat Exchangers: A Costly Problem. 15% of factory maintenance costs attributed to heat exchangers; 50% of that due to fouling.
    • iFactory Energy Optimization Platform (2026). Energy Wastage in Chemical Manufacturing Plants. Chemical plants waste 22–38% of purchased energy to undetected process inefficiencies.
    • Sight Machine / ARC Advisory Group, cited in Innovapptive (2024). Reduce Unplanned Downtime: A $20 Billion Challenge in the Chemical Industry.
    • Aberdeen Group Research, cited in WorkTrek (2025). Predictive Maintenance Cost Savings. Unplanned equipment failures cost an average of $260,000 per hour across industries.
    • McKinsey & Company (2019). Predictive maintenance: the wrong solution to the right problem in chemicals. Planned maintenance shutdowns cause OEE losses of 5–10%, twice as much as unplanned stoppages.
    • McKinsey & Company (2020). Predictive maintenance can reduce equipment downtime by up to 50% and lower maintenance costs by 10–40%. Cited across multiple industry sources.
  • When Steel Plants Run Smooth… and Still Lose Millions

    When Steel Plants Run Smooth… and Still Lose Millions

    When Steel Plants Run Smooth…
    and Still Lose Millions
    How prescriptive maintenance and Condition Monitoring Catch the Process Faults That DCS Alarms Miss

    Read Time: 8–9 minutes | Author – Kalyan Meduri

    Steel plant operator in safety gear monitoring PlantOS™ manufacturing intelligence dashboard on dual screens inside an active steel mill, AI-powered condition monitoring and prescriptive maintenance in real-time plant operations.

    Steel plants rarely fail loudly. They fail quietly. The tap happens on time. The cast continues. The rolls turn. And yet — energy consumption creeps up, emissions intensity worsens, refractory life collapses early, electrodes burn faster, operators compensate manually, and the cost is discovered weeks later on the power bill, fuel ledger, or sustainability report. This is the hidden reality of process-induced faults in steel manufacturing: faults born not out of breakdown, but out of operating drift. faults born not out of breakdown, but out of operating drift. Closing that gap requires prescriptive maintenance that goes beyond alarms — and condition monitoring that reads the signals conventional systems never correlate.

    Blast Furnace

    When furnace ‘stability’ quietly increases fuel rate

    The fault that hides in plain sight

    In blast furnace operation, uniform gas distribution through tuyeres is non-negotiable. Yet real furnaces rarely stay perfectly balanced. Small variations accumulate:

    • Coke degradation altering permeability
    • Uneven burden descent
    • Minor cooling-water deterioration at specific tuyeres
    • Drift in oxygen enrichment or PCI injection patterns

    These factors cause localized raceway instability, increasing thermal and mechanical stress on specific tuyeres well before any alarm fires.
    Studies and plant audits show that a 10–30 kg/thm increase in fuel rate often occurs without furnace instability. Cooling imbalance precedes burn through events by days to weeks. Operators compensate unknowingly by increasing blast or fuel input. The furnace keeps running — but at higher carbon and fuel cost.

    10–30 kg/thm

    Fuel rate increase — without any furnace instability alarm

    $0.8–1.2 M

    Production loss per tuyere burnout emergency

    A single tuyere burnout can cost $0.8–1.2 million in production loss during emergency replacement, yet most failures are preceded by detectable thermal and flow anomalies that go uncorrelated in standard DCS monitoring.

    How PlantOS™ intervenes

    PlantOS™ monitors correlated patterns, not single tags:

    • Spatial temperature deviations across tuyere cooling circuits
    • Raceways behaving differently despite ‘normal’ absolute values
    • Cooling delta and gas flow patterns that do not match expected furnace physics

    Instead of waiting for a threshold breach, PlantOS™ flags emerging imbalance clusters, prescribes targeted operating corrections (air distribution review, charging pattern adjustment, tuyere inspection), and allows operators to intervene before fuel rate inflation hardens into cost.

    Electric Arc Furnace (EAF)

    Power losses that don’t trigger trips — but blow up costs

    The fault no KPI captures

    EAF dashboards often show: Normal tap-to-tap time. Acceptable yield. No trips. Yet hidden beneath this ‘good operation’ is one of the most expensive drifts in steelmaking: arc instability.
    Arc instability is driven by:

    • Suboptimal electrode regulation
    • Poor foamy slag consistency
    • Scrap mix variability and uneven meltdown
    • Transformer tap and reactance mismatch

    Research shows unstable arcs increase kWh per ton, accelerate electrode erosion — and remain invisible to standard prescriptive maintenance systems that monitor only mechanical vibration and temperature thresholds.

    3-7%

    Increase in kWh/t from arc instability

    30 GWh/yr

    Excess electricity in a 1 Mtpa EAF shop at 30 kWh/t drift

    In 1 Mtpa EAF shop, even a 30 kWh/t drift equals 30 GWh of excess electricity per year, with no classical alarm to expose it.

    How PlantOS™ intervenes

    PlantOS™ correlates:

    • Electrode movement behavior

    • Current and voltage waveform variance

    • Oxygen and carbon injection patterns

    • Oxygen and carbon injection patterns

    It identifies non-obvious instability signatures — situations where absolute values are acceptable, but relationships are wrong — then prescribes arc-length corrections, slag chemistry stabilization actions, and power program optimization phases. These corrections restore energy coupling without slowing the heat delivering measurable AI for outcomes your energy manager can report.

    Reheating Furnaces

    How safety margins turn into permanent fuel loss

    The fault masked as a ‘safety margin’

    Reheating furnaces in rolling mills are notorious energy consumers. The most common process-induced fault is not burner failure – it is temperature overshoot used to hedge uncertainty.Root causes include: fuel calorific value fluctuation, poor synchronization between walking beam motion and firing zones, refractory degradation increasing wall losses, and manual setpoint buffers added to avoid underheating risk.
    This leads to 10-15% higher fuel consumption, increased scale formation (5-6% billet oxidation loss), and uneven metallurgical properties downstream – all while slabs still discharge ‘on temperature’.

    60–70%

    Of a rolling mill’s total thermal load consumed by reheating furnaces

    12–15%

    Fuel reduction achievable with correlated combustion optimization

    How PlantOS™ intervenes

    PlantOS™ overlays:

    • Zone-wise thermal profiles

    • Walking beam kinematics

    • Burner efficiency behavior

    • Historical slab temperature trajectories

    It detects systemic over-firing patterns – not momentary spikes – and recommends fine-grained combustion corrections that operators validate heat by heat. Plants using such correlation approaches routinely achieve 12–15% fuel reduction without risking rolling quality.

    Rolling Mills

    Throughput looks fine — energy intensity worsens

    The fault no one alarms for

    Rolling mills are assumed to be mechanically stable once commissioned. In reality:

    • Roll wear increases friction
    • Hydraulic imbalance raises resistance
    • Descaler inefficiency raises load
    • Misalignment causes motors to draw excess current

    10–15%

    Increase in energy per ton rolled from accumulated mechanical drift — with no effect on tonnage or schedule

    KPIs stay green. Energy intensity silently worsens. This is exactly the blind spot that AI predictive maintenance and continuous asset monitoring are designed to close catching drift before it becomes cost.

    How PlantOS™ intervenes

    PlantOS™ correlates:

    • Motor current vs rolling force

    • Hydraulic pressures vs strip dimensions

    • Descaling performance vs surface drag

    Instead of generic ‘high load’ alerts, it surfaces force–energy mismatches, guiding maintenance and process teams to correct the true cause — not the symptom.

    Utilities

    Compressed air & fans — the permanent energy leak plant heads underestimate most

    Utilities consume a substantial share of a steel plant’s total electricity. Compressed air leaks alone waste a significant proportion of generated air in poorly monitored systems. The challenge is not awareness — it is attribution. Which compressor? Which distribution leg? Which demand is artificial vs productive?

    20–30%

    Of a steel plant’s total electricity consumed by utilities

    25–40%

    Of generated compressed air wasted in poorly monitored systems

    How PlantOS™ intervenes

    PlantOS™ fingerprints:

    • Compressor load patterns

    • Pressure–flow relationships

    • Usage behavior tied to production states

    It exposes structural waste, not random leaks — allowing operators to attack the biggest energy drains first.

    Why DCS Alarms and Energy Reports Miss What Actually Matters, Why Traditional Monitoring Fails — and PlantOS™ Succeeds

    Steel plants already have data. What they lack is contextual intelligence. DCS alarms monitor thresholds. Energy reports aggregate results. Maintenance systems log failures. PlantOS™ works between them.


    It detects anomalies early (before thresholds), Correlates across process + energy + equipment, Prescribes operator-validated actions, Builds a living memory of “what worked where”. This approach aligns with proven industrial AI research showing that self-supervised, plant-scale anomaly detection dramatically outperforms static alarms in steel environments.

    The Gap That Remains — and Where It Lives
    01

    Steel plants are not data-poor. They are connection-poor. DCS platforms show what is happening in blast furnaces, EAFs, reheating furnaces, rolling mills, and utilities. Maintenance systems explain why assets eventually fail. Energy, power, and emissions reports show what already occurred — after the heat is tapped, the coil is rolled, and the bill is paid.
    What none of these answer — in real time — is the question that now carries direct financial, carbon, and regulatory weight:

    Which process deviation, interacting with which emerging asset condition, is inflating energy per ton of steel right now — and by how much?

    This is the gap where energy cost, carbon exposure, and reporting risk accumulate quietly.
    It is where disclosure confidence weakens, incentive eligibility is lost, and corrective action becomes reactive instead of economic.

    Closing this gap requires more than dashboards or alarms. It requires continuous correlation between process behavior, energy intensity, and asset health — followed by prescriptive actions that operators can validate and trust. This is precisely where Infinite Uptime’s Process Business, built on PlantOS™, operates. PlantOS™ identifies energy-relevant anomalies in steel operations while they are still recoverable:

    • Blast furnace gas-flow or tuyere imbalance
      before rising fuel rate hardens into sustained cost
    • EAF arc-stability degradation
      before kWh per ton increases compound across heats
    • Reheating furnace over-firing
      masked as safety margin while fuel efficiency can still be restored
    • Rolling-mill force–energy mismatches
      that never trip alarms because throughput never drops

    Critically, the system does not act in isolation. Every recommendation is reviewed, validated, and owned by operators on the floor. This is not automation replacing judgment — it is agentic intelligence amplifying it. Over time, each validated intervention becomes part of a growing operational memory: what worked, under which operating conditions, on which assets — and with what measurable impact on energy, cost, and carbon per ton of steel

    In the Field: What Operator-Validated Outcomes Look LikeID Fans02

    In an Aluminum Foil making company, PlantOS™ Process Diagnostic Report for Hindalco Mouda plant showing bearing temperature anomaly observation, AI-generated diagnosis, prescriptive maintenance recommendation, and corrective actions taken - operator-validated industrial AI output. PlantOS™ condition monitoring dashboard showing rolling oil temperature anomaly on Mill-4 before and after repair, trend charts with spray percentage and mill speed correlations, operator-validated prescriptive maintenance outcome. During rolling operations on Mill-4, the rolling oil temperature increased abnormally to approximately 55 °C, despite stable mill speed, load, and motor current. Comparative analysis showed the oil spray cooling system was inactive during rolling; comparison with similar runs confirmed spray non-operation as the root cause. Recommendation was precise: Enforce spray-cooling interlocks and alarms, validate spray controls, and set a minimum spray flow during rolling.

    Clear Business Impact stated prevention of accelerated oil degradation, excess chiller energy use (~226 kWh/event), equipment thermal stress, and improves MTBF while avoiding repeat energy and maintenance costs.

    This is not just a case study prepared for a presentation. This is Process Prescription Report generated by PlantOS™, acted & validated by plant operators, and time-stamped to the hour. The observation, diagnostic, recommendation, corrective action, and business impact are all in one record — auditable, explainable, and Reporting ready.

    PlantOS™ six-layer industrial AI platform architecture enabling predictive maintenance, manufacturing intelligence, process optimization, energy efficiency, and AI-driven production outcomes across smart manufacturing operations.

    The architecture above shows how PlantOS™ moves from raw plant data at the equipment and process layer (T1) through edge connectivity, platform execution, and prescriptive analytics (T2–T4), to decision planning, AI orchestration, and strategic governance (T5–T6). For cement energy management, the critical path runs through Process Canvas at T3 — which makes energy drift visible and explainable — and Process Prescript at T4, which converts correlated anomalies into timed operator actions. The 3–8% energy reduction validated at T4 is not a modelled estimate. It is an outcome confirmed by operators who acted on prescriptions, closed the loop, and logged the result.

    This is what positions PlantOS™ as Industrial Agentic AI for Operator-Validated Outcomes — not a monitoring layer, but a decision layer that closes the loop between data, human judgment, and measurable impact.

    Process-induced faults inflate energy, carbon, and cost while production looks stable. Infinite Uptime’s PlantOS™ closes that blind spot – not by replacing operators, but by giving them actionable, trusted insight exactly where conventional systems go silent. That is how energy is saved. That is how carbon is controlled.

    If you only see problems after the monthly report, you’re already paying for them!

    From Predictive Maintenance to Prescriptive Maintenance: What the Difference Means on the Plant Floor

    Predictive maintenance tells you a bearing will fail in 14 days. Prescriptive maintenance tells you exactly which bearing, which lubrication procedure, and which shift to do it in — before the failure window opens. The gap between these two is where millions are lost in steel plants. AI predictive maintenance systems flag the risk. Prescriptive AI closes it. PlantOS is built on the second — continuous condition monitoring and asset monitoring that generates operator-validated actions, not just alerts. That is AI for outcomes.

    Infinite Uptime’s PlantOS™ helps Steel manufacturing plants identify and correct energy-relevant process anomalies in real time — before they become carbon costs. To explore what this looks like for your operations

    Get in touch here →

    Frequently Asked Questions


    1. What are process-induced faults in steel manufacturing?

    Process-induced faults are deviations caused by operating conditions (load, control settings, system interactions) rather than mechanical failure. These faults often do not trigger alarms but lead to higher energy use, instability, and hidden cost losses.


    2. Why do DCS alarms fail to detect these faults?


    DCS systems monitor individual thresholds (temperature, vibration, pressure).
    They do not:

    • Correlate data across systems
    • Detect subtle deviations before limits are breached
    • Identify relationships between process, energy, and asset health


    3. How is prescriptive maintenance different from predictive maintenance?

    • Predictive maintenance: Tells you what might fail and when
    • Prescriptive maintenance: Tells you:
      • What exactly to fix
      • Why it is happening
      • What action to take
      • When to act

    PlantOS™ focuses on closing the loop from detection to action.


    4. How does PlantOS detect faults that other systems miss?


    PlantOS™ uses correlated, multi-variable analysis, looking at:

    • Process behavior
    • Energy consumption
    • Equipment signals

    Instead of isolated alerts, it identifies patterns and relationships that indicate early-stage deviations.These impacts are often invisible until reporting stage.


    5. Can PlantOS help with sustainability and ESG reporting?


    PlantOS™ doesn’t directly generate reports, but it provides:

    • Granular, asset-level energy data
    • Traceable operational records

    This data supports more accurate and defensible emissions calculations.


    6. How does PlantOS contribute to energy efficiency?


    Energy efficiency is not a standalone feature.
    It is an outcome of better operational decisions, including:

    • Optimized process control
    • Reduced drift
    • Corrected inefficiencies


    7. What makes PlantOS™ different from traditional monitoring systems?


    Traditional systems:

    • Detect failures
    • Trigger alarms

    PlantOS™:

    • Detects early deviations
    • Explains root cause
    • Prescribes exact actions
    • Tracks outcomes

    Read More on Prescriptive Maintenance and Condition Monitoring

    References:

    • The Operation of Contemporary Blast Furnaces | Springer Nature Link
    • Causes and treatment measures for abnormal blast furnace conditions
    • Blast Furnace Tuyere Maintenance: Inspection, Replacement & Failure Prevention Guide
    • Arc Stability and Power Input in the EAF | LinkedIn
    • Energy Loss Analysis in Steel Manufacturing
    • Reheat Furnace Analytics: Burner, Refractory & Walking Beam System Guide
    • Reduce Consumption of Rolling Mill Reheating Furnace
    • ijaerv12n23_48.pdf
    • Improving Compressed Air System Performance: A Sourcebook for Industry
    • Handsfree, Fully Autonomous Anomaly Detection AI
  • Prescriptive AI for U.S. Cement

    Prescriptive AI for U.S. Cement

    Prescriptive AI for U.S. Cement
    Closing the Margin and Sustainability Gap Predictions Miss

    Why prescriptive AI not predictive AI is the lever U.S. cement plants are missing. How
    PlantOS turns silent process drift into operator-validated outcomes that simultaneously improve
    margin, emissions intensity, and audit-ready compliance under U.S. sustainability frameworks.

    Read Time: 8–9 minutes | Author – Kalyan Meduri

    Cement plant control room with prescriptive AI analytics monitoring rotary kiln operations and emissions

    The U.S. cement industry has spent the better part of a decade investing in industrial AI. DCS platforms
    are connected. Maintenance systems are digitized. Predictive models flag emerging faults. And yet, on
    most plants we walk into, three to eight percent of the energy bill is being spent on inefficiency that no
    system has surfaced quiet process drift hiding in plain view of every monitoring tool the plant owns.

    What is new: this same drift now directly affects more than margin. It inflates reported Scope 1 and
    Scope 2 emissions intensity, weakens Environmental Product Declarations (EPDs), and creates disclosure
    risk across Buy Clean programs and California’s climate reporting regime.

    This is the gap between predictive AI and prescriptive AI — and it has become the single most expensive
    blind spot in U.S. cement operations.

    Predictive AI tells a plant what is likely to happen. Prescriptive AI — AI for outcomes — tells the operator
    what to do about it, with a specific, validated, time-stamped action calibrated to the asset and the
    process. The first is a forecast. The second is a decision. The first generates alerts. The second generates
    results.


    Prediction ≠ Outcomes.

    For U.S. cement producers operating in 2026 — under California’s August disclosure deadline,
    hyperscaler procurement pressure on embodied carbon, EU CBAM exposure on exports, and the simple
    fact that energy is the largest controllable cost in cement after raw materials — the difference between
    prediction and prescription is no longer academic. It is the difference between knowing about a problem
    and closing it.

    It now determines whether a plant’s sustainability data is defensible — or just estimated.

    The Outcome Gap

    Where Cement Plants Are Connection-Poor, Not Data-Poor01

    Most U.S. cement plants are not data-poor. They are connection-poor. DCS platforms show what is happening. Maintenance systems explain why assets fail. Energy and emissions reports show what already occurred. Predictive AI overlays add a fourth signal: what may happen next.
    What none of these answer in real time is the question that now carries both financial and sustainability weight:

    Which process deviation, interacting with which emerging asset condition, is inflating energy intensity right now — and what should the operator do about it in the next two hours?

    This question matters not only to cost control, but to:

    • Energy intensity metrics feeding Scope 1 and Scope 2 disclosure
    • Plant-level EPD accuracy for Buy Clean tenders
    • Assurance defensibility under California SB 253
    • Carbon benchmarks applied under EU CBAM default values

    These are prescriptive questions. Dashboards cannot answer them. Alerts cannot close them. Only prescriptive AI that links process behavior → energy intensity → operator action can.

    This is the work prescriptive AI for outcomes is built to do.

    Predictive AI vs. Prescriptive AI in Cement Operations02

    Reliability Condition Net Zero Impact Mechanism
    Stable kilns Optimal fuel consumption, lower specific energy Consistent thermal profile reduces excess fuel burn
    Reduced unplanned breakdowns Lower waste, reduced reprocessing, fewer emission spikes Eliminates energy-intensive restart cycles
    Consistent operations Predictable emissions, reliable ESG reporting Steady-state process enables accurate carbon accounting
    Higher uptime → higher throughput Amortises fixed-cost decarbonisation investments across more tonnes Spreads CAPEX of green upgrades over greater output volume

    The Energy Arithmetic

    Where Process Drift Quietly Inflates Cost01

    Any process deviation that raises GJ per tonne of clinker or kWh per tonne of cement increases cost and mechanically increases emissions intensity under U.S. and international accounting methodologies, regardless of fuel mix or offset strategy.

    A plant may be compliant, permitted, and operating steadily and still deteriorating against Buy Clean thresholds, customer EPD benchmarks, and insurer or lender intensity screens.

    $500K–$700K

    Annual thermal-only margin leak from a 0.1 GJ/tonne kiln drift on a one-million-tonne-per-year
    line, at typical U.S. solid-fuel costs. Including embodied-carbon exposure in tender outcomes and
    California disclosure, fully-loaded impact can multiply two to four times.

    Process drift does not announce itself. It does not trigger downtime, alarms, or permit exceedances. It accumulates across four asset families that prescriptive AI has to address simultaneously.

    Kilns and Calciners — Burning Fuel Without a Warning

    Kiln instability remains the least visible source of thermal energy waste in U.S. cement plants. False air ingress, cyclone pressure imbalance, alternative fuel calorific variability, and swings in raw meal chemistry can push specific heat consumption well above benchmark. A kiln drifting from ~680 kcal/kg of clinker toward 750 kcal/kg represents roughly 10% higher fuel consumption — without triggering a single alarm. By the time monthly reports are reviewed, the burn is already in the books.

    Vertical Roller Mills — Sensitivity at Scale

    A stable VRM circuit consumes 20–23 kWh per tonne of cement. Under subtle instability — grinding bed oscillation, separator inefficiency, excessive circulating load — consumption climbs to 25–30 kWh per tonne. For a one-million-tonne-per-year mill, a sustained 3 kWh/tonne drift equates to 3 GWh of excess electricity annually. The process does not stop. Output appears normal. The inefficiency surfaces only in hindsight — exactly the kind of drift predictive AI underweights and prescriptive AI is built to catch.

    Ball Mills — The Most Misleading Energy Risk

    Ball mills present a particularly dangerous blind spot in legacy U.S. plants. Their inefficiency is structurally concealed by design. Suboptimal media charge, incorrect separator settings, high recirculation ratios, liner wear leading to slip rather than impact breakage, and pinion-girth gear misalignment can collectively raise power consumption 15–20% above optimal — often with no measurable loss in throughput. Specific energy consumption that should sit in the 35–42 kWh per tonne range quietly drifts higher. KPIs remain nominal. Availability remains high. The cost accumulates unnoticed.

    Fans — Silent Multipliers

    Fans account for 20–30% of total plant electrical load. Fouling, duct buildup, damper misalignment, or mechanical imbalance can increase fan power draw 10–15% without affecting production stability. These losses rarely show up in day-to-day operational discussions. They appear later in energy intensity metrics — long after the opportunity to intervene cheaply has passed.

    The 2026 Pressure Map

    Why Margin Pressure Now Comes from Three Directions
    01

    The federal climate apparatus that producers were preparing for in 2023 has been substantially rolled back. The SEC’s climate disclosure rules are no longer being defended. EPA’s Social Cost of Carbon is being phased out of regulatory analysis. IRA-era cement and concrete decarbonization grants have been canceled or terminated. For producers who built compliance plans around those frameworks, acute federal pressure has eased.

    What has not eased and is in many ways tightening is pressure from three other directions:

    01. Customers.

    Data center hyperscalers, federal GSA buyers, and state-level Buy Clean programs in California, New York, New Jersey, Colorado, Maryland, Oregon, Washington, and Minnesota are placing active price-signal weight on low-embodied-carbon concrete. Plants that can document operator-validated energy intensity win these tenders. Plants that cannot, don’t.

    02. California is now the de facto national disclosure regulator.

    SB 253 requires U.S. companies above $1B in revenue doing business in California to disclose Scope 1 and Scope 2 emissions, with the first reporting deadline of August 10, 2026. CARB has signalled enforcement discretion for the first reporting cycle, but the disclosure obligation is binding. CARB has explicitly named cement production as a priority sector for Scope 3 phase-in in 2027. The state’s standing mandate to cut cement emissions 40% by 2035 (relative to 2019) and reach net-zero by 2045 is the binding long-term target for any producer with California exposure.

    03. Trade and capital markets are pricing carbon even where Washington is not.

    The EU’s Carbon Border Adjustment Mechanism applies default emission values starting in 2026, raising landed cost for U.S. clinker and cement exporters that cannot supply verified intensity data. Insurers and lenders increasingly price emissions intensity into capacity, rate, and ESG covenants.

    None of these requires a federal carbon price to translate into real dollars. They already show up in tender win rates, in insurance premiums, in lender covenants, and in the narrowing list of acceptable suppliers for the largest construction buyers in North America.

    A plant operating with poorer energy efficiency carries a structurally higher emissions intensity regardless of fuel mix or geography and faces higher friction at every one of these touchpoints.

    The Decision Layer

    Sustainability as an Output, Not a Report01

    Every PlantOS prescription produces:

    • A time-stamped operational action
    • A measurable energy outcome
    • A verified reduction in emissions intensity
    • An auditable record tied to real process behavior

    This is exactly the level of evidence U.S. producers increasingly need for SB 253 disclosure readiness, EPD verification, Buy Clean compliance, and lender assurance — not estimates, not averages, but operator-validated outcomes.

    Prescriptive AI therefore becomes a sustainability control system, not a reporting add-on.

    How the Loop Closes

    Closing the gap between data and outcome requires more than monitoring. It requires continuous correlation between process behavior, energy intensity, and asset health followed by prescriptive actions that operators can validate and trust.

    This is precisely where Infinite Uptime’s Process business, built on PlantOS, operates.

    PlantOS identifies energy-relevant process anomalies while they are still recoverable: VRM separator drift before it hardens into systemic inefficiency, kiln heat imbalance while fuel efficiency can still be restored, chronic ball mill over-consumption that never trips an alarm because throughput never drops. Two PlantOS capabilities form the critical path:

    Process Canvas makes energy drift visible and explainable across kiln, mill, and fan systems in a single correlated view.

    Process Prescript converts correlated anomalies into timed operator actions auditable, executable, and tied to a measurable outcome.

    Every recommendation is reviewed, validated, and owned by operators on the floor. This is not automation replacing judgment. It is agentic AI amplifying it. Each validated action becomes part of the 99% Trust Loop — a growing operational memory of what worked, under what conditions, on which assets.

    The 3–8% energy reduction validated across deployed plants is not a modeled estimate. It is an outcome confirmed by operators who acted on prescriptions, closed the loop, and logged the result.

    This is what positions PlantOS as Industrial Agentic AI for operator-validated outcomes — not a monitoring layer, but a decision layer.

    The Field Record

    What Operator-Validated Outcomes Look Like
    01

    PlantOS is deployed across one of the largest cement and steel reference footprints globally — 844+ plants across 26 countries, 149 enterprises, and 9 verticals. Within that footprint, JSW Steel alone has eliminated 30,096 hours of downtime through 8,610 AI-assisted work orders, with 93% prescription adoption. Star Cement operates at 99% prescription adoption, with 10x ROI under six months.

    The outcome below is representative of how prescriptive AI for outcomes actually appears in a Process Prescription Report:

    Field Outcome  ·  Star Cement, SCL Line 2

    Coal Extraction Fault — Kiln Firing System Trip

    On 9 September at 18:35, the kiln stopped. PlantOS diagnosed the cause within the same operational window: the MB firing system had tripped because rotor scale current reached 25 amps — the H2 limit — due to material jamming in the coal extraction path from bin to rotor.

    The prescription was specific: adjust aeration air pressure for bin and rotor; implement regular rotor cleaning to prevent recurrence. The operator validated and executed. Rotor aeration adjusted to 0.8 kg/cm². Baby bin aeration set to 2.5 kg/cm². Rotor gap confirmed at 0.3–0.35 mm in discussion with the OEM.

    Customer comment, logged: “Corrective action found effective.”

    Approximately 2,000 tonnes of production protected. Four breakdown hours saved.

    This is not a case study prepared for a presentation. It is a Process Prescription Report generated by PlantOS, acted on and validated by plant operators, time-stamped to the hour. The observation, diagnostic, recommendation, corrective action, and business impact sit in one auditable record — explainable, traceable, and ready for whatever assurance regime a producer needs to satisfy. This is the type of primary operational evidence increasingly required in:

    • California climate disclosures
    • Low-carbon procurement qualification
    • Third-party EPD verification
    • ESG audits tied to financing

    The Operating Reality

    Process Control Is Margin Control
    01

    In the U.S. operating environment, process control is margin control. It is also sustainability control and, increasingly, the foundation of customer access, disclosure defensibility, and competitive position.

    The plants that close this gap early by moving from predictive AI to prescriptive AI for outcomes will operate with lower unit cost, stronger tender economics, and a more defensible carbon footprint for the customers who are now actually pricing it.

    The plants that do not will continue to discover the penalty financial and reputational only after it has already been paid.

    See it on your plant

    Find the 3–8% energy — and emissions intensity — your DCS isn’t surfacing.

    Infinite Uptime’s PlantOS helps U.S. cement producers identify and correct energy-relevant process anomalies in real time — before they become margin, customer, or compliance costs.

    Request a Plant Walkthrough  →

    Read More on Industrial Energy Efficiency

  • Process Anomalies to Carbon Penalties: The Hidden Energy Story Inside European Cement Plants

    Process Anomalies to Carbon Penalties: The Hidden Energy Story Inside European Cement Plants

    Process Anomalies to Carbon Penalties: The Hidden Energy Story Inside European Cement Plants
    How silent process drift inside cement plants became a priced carbon risk — and why the answer lies in the gap between what plants measure and what they miss.

    Read Time: 5–6 minutes | Author – Kalyan Meduri

    European cement plant with PlantOS industrial energy optimization reducing hidden process drift, carbon emissions, and CBAM penalties

    Europe’s cement industry is entering a new operating reality, and it has little to do with market demand or fuel prices. With EU ETS carbon prices now exceeding €80–90 per tonne of CO₂ — and the Carbon Border Adjustment Mechanism becoming financially enforceable from January 2026 — energy inefficiency has crossed a threshold. It is no longer an internal operational concern. It is a priced carbon exposure, one that now directly shapes margins, export viability, and competitive positioning.


    What makes this exposure difficult to manage is not the absence of technology. Most European cement plants already run DCS systems, maintenance platforms, and periodic energy reports. The problem is where the losses actually originate.


    Most excess energy and carbon emissions in cement plants do not come from failures. They do not come from downtime, broken equipment, or obvious process upsets. They come from anomalies that persist quietly while the plant appears stable — gradual drifts in process behaviour that inflate specific energy consumption week over week, with no alarm, no throughput loss, and no visible signal until the carbon cost is already locked in.

    The Carbon Arithmetic of Cement Production

    Cement manufacturing accounts for roughly 6–8% of global CO₂ emissions — approximately 2.4 gigatonnes annually. The sources are well understood: chemical emissions from limestone calcination, and the energy intensity of thermal and grinding operations. In a typical integrated plant, thermal energy to the kiln and calciner accounts for 60–65% of total consumption; electrical energy for grinding, fans, and utilities makes up the remaining 35–40%.


    The regulatory implication of this split is direct: any process deviation that increases GJ per tonne of clinker or kWh per tonne of cement also increases Scope 1 or Scope 2 emissions — even when throughput remains unchanged. There is no operational buffer between process inefficiency and carbon liability.


    The EU BAT benchmark for a modern precalciner kiln sits at 3.0–3.2 GJ per tonne of clinker. A deviation of just 0.1 GJ per tonne on a one-million-tonne-per-annum clinker line translates to more than 100,000 GJ of excess energy annually and 7–9 kilotonnes of additional CO₂. At current EU ETS prices, that is a seven-figure carbon cost from a deviation that registers nowhere in standard KPI dashboards.

    Where Energy Quietly Escapes

    Kilns and Calciners: Burning Fuel Without a Warning

    Kiln instability is among the least visible sources of thermal energy waste. False air ingress, cyclone pressure imbalance, alternative fuel calorific variability, and raw meal chemistry swings — particularly in lime saturation factor and silica modulus — can push specific heat consumption from the BAT benchmark of around 680 kcal per kilogram of clinker to 750 kcal or beyond. That is approximately 10% higher fuel consumption, with no production alarm and no throughput signal. By the time monthly energy reports capture the drift, the EU ETS liability has already accrued.

    Vertical Roller Mills: Sensitivity That Operates at Scale

    A well-operated VRM grinding circuit consumes 20–23 kWh per tonne of cement. Under unstable conditions — grinding bed instability, separator cut-size drift, excess circulating load — that figure climbs to 25–30 kWh per tonne. For a one-million-tonne-per-annum cement mill, a sustained drift of just three kWh per tonne represents 3 GWh of excess electrical consumption annually: roughly 1.2–1.5 kilotonnes of additional CO₂ at EU grid intensities. The process does not stop. Output continues. The energy inflation simply does not appear until the bill arrives.

    Ball Mills: The Most Misleading Energy Risk

    Ball mills represent a particular blind spot in legacy plants. Unlike VRMs, their inefficiency is structurally hidden. Sub-optimal grinding media charge, incorrect separator settings, high recirculation ratios, worn liners causing slip rather than breakage, and pinion-girth gear misalignment can collectively drive mill power consumption 15–20% above optimal — with no noticeable throughput loss and no immediate alarm. Specific energy typically ranges from 35–42 kWh per tonne under normal conditions. Under silent drift, that ceiling is regularly exceeded. KPIs appear normal. The plant appears stable. Scope 2 emissions quietly increase.

    Fans: Silent Multipliers Across the Plant

    Fans consume 20–30% of a cement plant’s total electrical load. Fouling, duct build-up, or mechanical imbalance can increase fan power draw by 10–15%. These losses almost never affect availability or throughput — they affect only energy intensity, and they accumulate invisibly across shift reports and monthly aggregations.

    CBAM Changes the Penalty Structure

    What CBAM introduces — beyond the carbon price itself — is a fundamentally different penalty logic. Under the previous operating model, carbon costs were partially absorbed, partially passed through, and managed as a macro-level cost line. CBAM changes this: from January 2026, cement and clinker imports face EU ETS-linked pricing based on embedded emissions, calculated at the level of the production process.


    The implication is precise and consequential. CBAM does not penalise geography or fuel choice alone. It penalises process inefficiency. A plant running at 750 kcal per kilogram of clinker rather than 680 carries a structurally higher embedded emissions figure — and a structurally higher CBAM liability — regardless of where it is located or what fuel it burns.

    CSRD: From Reported Numbers to Demonstrated Control

    The Corporate Sustainability Reporting Directive adds a further dimension that is frequently underestimated. Under CSRD, cement producers are required to disclose not only energy intensity metrics but evidence of operational controls — demonstrable governance over the accuracy and reliability of sustainability data.


    Manual, monthly energy aggregation cannot satisfy this requirement. It cannot explain why grinding instability occurred over a 48-hour window, why fan load trended upward across three shifts, or how refractory heat loss in the kiln contributed to a quarterly Scope 1 increase. Process-level explainability is now a regulatory expectation, not a reporting aspiration.

    The Gap That Remains — and Where It Lives

    European cement plants are not operating without data. They are operating with data that does not connect.


    DCS systems show what is happening in the process. Maintenance systems explain why equipment eventually fails. Energy reports show how much energy was consumed — after the fact. What none of these provide is an integrated, real-time answer to the question that now carries direct financial consequence:


    Which process deviation, combined with which emerging asset condition, is inflating kWh per tonne or kcal per kilogram right now — and by how much?


    This is the gap where CBAM exposure accumulates and where CSRD obligations become difficult to defend. Closing it requires something that monitoring dashboards and periodic reports were never designed to deliver: continuous correlation across process behaviour, energy intensity, and asset health — followed by a recommendation that an operator can act on, validate, and trust.


    This is precisely where Infinite Uptime’s Process Business, built on PlantOS™, operates.


    PlantOS™ works at the process-energy interface — where deviations are still small, corrections are still low-cost, and carbon penalties can still be avoided. It identifies VRM separator drift before a sustained energy increase hardens into a reporting obligation. It flags kiln heat imbalance while fuel efficiency is still recoverable. It surfaces chronic ball mill over-consumption that no conventional dashboard has flagged — because throughput never dropped and no alarm ever fired.


    Critically, the system does not act in isolation. Every recommendation is designed to be reviewed, validated, and owned by the operator on the floor. The outcome is not automation displacing judgment — it is agentic intelligence that accelerates it. Over time, each intervention that an operator validates becomes part of a continuously improving decision fabric: a record of what worked, under which conditions, on which assets.


    The following Process Diagnostic Report, drawn from live cement plant deployments, show what this looks like in practice.

    In the Field: What Operator-Validated Outcomes Look Like

    Star Cement — Kiln Firing System Trip, Coal Extraction Fault


    PlantOS process diagnostic report for Star Cement showing kiln trip analysis, prescriptive maintenance actions, production savings, and industrial energy optimization outcomes

    At Star Cement, SCL Line 2 Kiln stopped on 9 September at 18:35. PlantOS™ diagnosed the cause within the same operational window: the MB firing system had tripped because rotor scale current reached 25 amps — the H2 limit — due to material jamming in the coal extraction path from the bin to the rotor. The recommendation was precise: adjust aeration air pressure for the bin and rotor; implement regular rotor cleaning to prevent recurrence.


    The operator validated and executed: Rotor Aeration adjusted to 0.8 kg/cm², Baby Bin Aeration set to 2.5 kg/cm², rotor gap confirmed at 0.3–0.35mm in discussion with the OEM. Customer comment logged: “Corrective action found effective.”


    Business impact: approximately 2,000 tonnes of production protected, four breakdown hours saved.


    This is not just a case study prepared for a presentation. This is Process Prescription Report generated by PlantOS™, acted & validated by plant operators, and time-stamped to the hour. The observation, diagnostic, recommendation, corrective action, and business impact are all in one record — auditable, explainable, and CSRD-ready.


    PlantOS Path to Value six-layer industrial AI platform for predictive maintenance, industrial energy optimization, process analytics, and cement plant efficiency improvement

    The architecture above shows how PlantOS™ moves from raw plant data at the equipment and process layer (T1) through edge connectivity, platform execution, and prescriptive analytics (T2–T4), to decision planning, AI orchestration, and strategic governance (T5–T6). For cement energy management, the critical path runs through Process Canvas at T3 — which makes energy drift visible and explainable — and Process Prescript at T4, which converts correlated anomalies into timed operator actions. The 3–8% energy reduction validated at T4 is not a modelled estimate. It is an outcome confirmed by operators who acted on prescriptions, closed the loop, and logged the result.

    This is what positions PlantOS™ as Industrial Agentic AI for Operator-Validated Outcomes — not a monitoring layer that surfaces data, but a decision layer that closes the loop between process intelligence, human judgment, and measurable operational impact.

    In the CBAM and CSRD era, process control is carbon control. The plants that close this gap first will carry a lower embedded emissions figure, a stronger regulatory position, and a structurally more defensible cost base.
    The plants that do not will continue to discover the penalty after it has already been paid.Infinite Uptime’s PlantOS™ helps European cement producers identify and correct energy-relevant process anomalies in real time — before they become carbon costs.


    To explore what this looks like for your operations,
    see here:
    Get in touch here .

    Thank you for your interest in PlantOS™ Prescriptive AI.

    Enter your official work email to unlock the World’s Most User-Validated Case Study.[contact-form-7 id=”93f3a5d” title=”pdf downlaod-blog-Plant Reliability Beyond Mechanical Faults”]

    Read More on Industrial Energy Efficiency

  • Prescriptive AI for Recovery Boilers, Refiners &  Paper Machines

    Prescriptive AI for Recovery Boilers, Refiners & Paper Machines

    Prescriptive AI for Recovery Boilers, Refiners & Paper Machines
    Enabling Semi-Autonomous Pulp & Paper Mills

    Read Time: 8–9 minutes  | Author – Kalyan Meduri

    Prescriptive AI in pulp and paper mill showing recovery boiler, refiner system, and paper machine for improved reliability and energy efficiency

    Key Highlights

    • How fibre-cost pressure and sustainability commitments are quietly undermined by reliability  failures on recovery boilers, refiners, and paper machine dryer sections. 
    • Why traditional predictive tools stall at alarms — leaving mill teams to interpret signals rather  than execute the right action in high-stakes, high-temperature environments. 
    • How PlantOS™ orchestrates vertical-trained, agentic, explainable AI across mechanical, electrical,  and process-induced failure modes — turning streaming equipment and process data into a single,  trusted source of truth for prescriptive maintenance and energy-efficient operation. 
    • What Prescriptive AI looks like on the Plant floor: fewer sheet breaks, higher availability, lower  kWh/ton — validated by operators, not dashboards. 

    Sustainable pulp and paper manufacturing is no longer a brand statement — it is a boardroom mandate.  Regulators, brand owners, and customers want lower kWh/ton, lower fibre loss, and auditable  reliability, all while mills stay cost-competitive. 


    The inconvenient truth: none of it holds if the recovery boiler, refiners, and paper machine — the assets  that sit at the intersection of reliability, throughput, and energy intensity — keep failing in ways nobody  saw coming. 


    A boiler feed pump bearing degrading overnight. A refiner motor developing an inner race defect mid campaign. A dryer cylinder bearing running hot. One fault, and fibre, steam, and tonnage are lost in a  single cascade 


    That is exactly where Prescriptive AI — and the PlantOS™ 99% Trust Loop — change the script.

    The Sustainable Mill Mandate Meets Operating Reality01

    Consider a recovery boiler forced into an unplanned load reduction when a feed pump motor bearing  fails without warning. Steam balance collapses, the paper machine loses dryer capacity, reel ends go off spec, and the mill compensates with auxiliary firing that drives up both kWh/ton and emissions  intensity. A refiner motor failure mid-grade compounds this — off-quality stock, energy penalties from  running above the efficiency inflection point, and production losses that ripple through the stock prep  line. 


    Sustainable mill operations succeed when reliability enables energy efficiency — not as a side effect,  but as a concrete P&L lever with measurable energy savings per ton produced.

    Why Traditional Predictive Tools Stall at Alarms02

    Most mills today are not short of data. Vibration sensors on fans and motors, temperature monitoring  on dryer bearings, motor current and load feedback on refiners, plus process measurements like  freeness, consistency, steam pressure, and sheet moisture are all streaming somewhere. Traditional  predictive tools do a decent job of turning raw signals into alerts: 

    • “Motor DE bearing acceleration trending above threshold.” 
    • “Refiner motor vibration velocity fluctuating.” 
    • “Dryer cylinder bearing temperature rising.” 

    The problem is what happens next. 

    In many cases, these tools leave engineers with a red or yellow signal and a generic recommendation:  “Inspect asset,” “Plan maintenance,” or “Check lubrication.” In a mill running three grades across two  machines under steam-balance constraints, that is not enough.  

    The result: 

    • Alarm fatigue: too many alerts with too little context. 
    • Low trust: operators remember every false alarm, not the saves. 
    • Outcome gap: insights exist, but they do not reliably translate into timely, precise, executed  actions. 

    You remain in a world of predictive signals without a prescriptive path to prevent the next boiler trip,  refiner failure, or sheet break with confidence.

    Mill failures are rarely purely mechanical in nature. A bearing defect (mechanical), a motor current  excursion (electrical), and a consistency or steam-pressure swing (process-induced) often coexist on  the same asset in the same shift. Any tool that handles only one dimension will keep missing the  causal chain.

    PlantOS™ and the 99% Trust Loop 03

    PlantOS™ — the world’s most user-validated Prescriptive AI — was built to close this outcome gap, not  to produce more dashboards. Under the hood, PlantOS™ orchestrates a network of agentic, explainable  AI models, vertical-trained on pulp and paper, metals, mining, cement, chemicals, and other asset intensive sectors. It brings vibration, motor current, temperature, and process signals into one reasoning  layer — so mechanical, electrical, and process-induced failure modes on the same asset are evaluated  together, not in isolation.  


    The result is a single prescription, with zero guesswork on what to do next. 


    At the heart of PlantOS™ is the 99% Trust Loop — a closed loop combining fault prediction and data  contextualization, prescriptive recommendations, operator validation, and outcome tracking. 

    For a recovery boiler, refiner line, or paper machine dryer section, the Trust Loop closes like this: raw  equipment and process streams are contextualized by vertical AI models →a high-accuracy fault  prediction is generated with the underlying evidence made  

    visible to the operator →a specific, actionable prescription is  delivered →the operator validates and executes →the  outcome is tracked and fed back to sharpen the model.


    A living  reliability system, not a static rules engine. 


    Every PlantOS™ prescription is built on the same explainable  logic — a clear observation, a named diagnosis, a specific recommendation, and a quantified business impact.


    The same  structure applies whether the root cause is mechanical,  electrical, or process-induced.


    vEdge 3XT sensors mounted on the DE and NDE of the Boiler Feed Pump

    Recovery Boiler — From Surprise Failures to
    Predictable
    Availability
    04

    Why it matters. The recovery boiler and its auxiliary train — boiler feed pumps, ID and FD fans, precipitator drives, soot  blowers — sit at the top of every pulp mill’s risk register. 

    Availability here is the single largest determinant of integrated mill output, steam balance across the  paper machine, and increasingly, of audited sustainability performance. 

    Where it fails. Feed pump motor bearings are a classic pressure point. They run continuously, across  load swings and firing cycles, and a single overnight degradation — most often a lubrication issue on the  drive-end bearing — can escalate into a forced load reduction, a steam shortfall, and a paper machine  slowdown within hours. Legacy tools see a vibration spike and flag it. They rarely tell the engineer  whether it is load-induced, lubrication-related, or the start of a genuine defect — and they almost never  tell them what to do about it or when. 

    What Prescriptive AI does differently. A live prescription from a leading Pulp & Paper Manufacturing  Plant in India shows the difference in practice.  

    • Observation: Total acceleration at the boiler feed pump motor drive-end bearing jumped from  38 to 252 (m/s²)² inside a single day, with a raised noise floor in the vibration spectrum.  
    • Diagnosis: PlantOS™ did not stop at the anomaly. It identified inadequate lubrication on the  Drive End (DE) bearing as the specific cause 
    • Recommendation: Issued a clear action — re-lubricate the motor DE and NDE bearings.
    • Business Impact: 6 hours of unplanned downtime saved.  

    The site reliability engineer executed the greasing. Post-repair trends verified a 29% reduction in  vibration velocity.


    Before and after repair vibration spectrum analysis of boiler feed pump showing reduced velocity and improved equipment reliability with prescriptive AI maintenance

    That is the shift: from a flashing alert to a named fault, a named action, a named owner, and a  measured outcome.

    Refiners — Where Reliability, Quality, and
    kWh/Ton
    Converge05


    vSense 1XT sensors mounted on the DE and NDE of the Refiner Motor – 11kV

    Why it matters. Disc and conical refiners sit at the most energy-intensive point of the stock prep line. They do not justkeep the mill running; they shape the sheet.Freeness,sheetstrength, and specific energy consumption are all influenced by refiner health – which means refiner reliability and refiner energy efficiency are not two problems, they are one.

    Where it fails. Refiner failure signatures are rarely purely mechanical. A bearing defect often shows up first in the electrical current trace as load drift, becomes visible in vibration as it progresses, and only then begins to affect freeness downstream. Traditional tools that look at one dimension at a time – vibration alone, or motor current alone – tend to catch the fault too late, and usually without enough context to prescribe the right intervention.

    What Prescriptive AI does differently. A live prescription from an 11 kV refiner motor at a leading paper mill in the Middle East illustrates the point.

    • Observation: PlantOS™ detected fluctuating vibration velocity at the refiner non-drive-end  bearing, with the spectrum showing inner race defect frequencies (BPFI at 357.51 Hz) and non synchronous components.  
    • Diagnosis was specific: an inner race defect on the bearing – not a generic anomaly.  
    • Recommendation was equally specific: re-lubricate as an immediate corrective step, plan a  bearing replacement at the next available stop, and inspect the refiner disc condition during the  same window.  
    • Business Impact: six hours of potential unplanned downtime prevented, with the heavier  intervention folded into a planned stop instead of forced as a reactive one. 

    The outcome is a refiner line that delivers consistent freeness at the lowest achievable kWh/ton – with  bearing and plate life extended against real process conditions, not conservative calendar planning. 

    Paper Machine Dryer Section — From Sheet
    Breaks to Scheduled Interventions06


    Paper machine dryer cylinder roll with drive system and sensors for condition monitoring and prescriptive AI-based reliability in pulp and paper mill
    vSense 1XT sensors mounted on the DE of the Double Cylinder Roll – Dryer Machine

    Why it matters. The dryer section is the longest, hottest, and most unforgiving stretch of the paper machine. Dryer cylinder bearings, felt roll imbalance, steam joint integrity, and drive gearbox health each represent a direct path to a sheet break. And in the dryer section, a sheet break does not end when the sheet is rethreaded – it cascades into lost steam stability, off-quality reel ends, and recovery times that routinely exceed an hour on a fast machine.

    Where it fails. Dryer bearings typically warn before they fail – through rising temperature, subtle vibration change, or both. The challenge is interpretation. A rising bearing temperature can mean inadequate lubrication, a coolingsystem problem, or an early-stage bearing defect, and each demands a different corrective path. Traditional alerts flag the symptom without guiding the engineer to the right root cause or the right moment to act.

    What Prescriptive AI does differently. A live prescription from a leading Turkish paper mill shows the Prescriptive intelligence at work.

    • Observation: PlantOS™ detected a sudden temperature rise to 129.5°C (265°F) at the Dryer  Cylinder Roll-non-drive-end bearing.  
    • Diagnosis: Rather than issue a generic “inspect asset” alert, the platform prescribed a logical,  prioritized sequence. 
    • Recommendation: verify lubrication first; if adequate, check the cooling system and plan  additional cooling if required; if both are satisfactory, plan a bearing inspection at the next  available opportunity. 


    The mill’s reliability engineer followed the sequence, increased the oil flow rate, and closed the  intervention with no abnormality observed.  


    The business impact: 8 hours of unplanned downtime saved. 


    Dryer repair outcome: temperature sensor data showing irregular spikes before repair vs stable 200°C readings after fix.

    The prescriptive advantage in the dryer section is not just detection – it is scheduling intelligence.  PlantOS™ sequences interventions against planned grade changes, wire and felt changes, and cleaning  stops, so fixes land inside stops the mill was already taking, not as emergencies that cool the machine.

    Preventing Unplanned Stops — Equipment and Process Reliability as One07

    The three cases above share a pattern. Each prescription is specific, explainable, and tied to a quantified  outcome — and each one cuts across what would traditionally be treated as separate domains. 


    Unplanned stops in a pulp and paper mill rarely originate in a single component. A sheet break in the  dryer section is as likely to trace back to steam pressure instability from a recovery boiler auxiliary as it is  to a dryer bearing. A refiner trip is as likely to reflect a stock consistency excursion upstream as a plate  or bearing issue. A motor bearing failure is as likely to expose itself first through an electrical current  signature as through vibration. Traditional approaches silo these subsystems – boiler here, stock prep  there, paper machine elsewhere; and within each silo, mechanical here, electrical there, process data  somewhere else – creating diagnostic blind spots that prescriptive AI eliminates. 


    PlantOS™ delivers Equipment + Process Reliability as a single source of truth by correlating: 

    • Mechanical data: Vibration spectra, bearing defect frequencies (BPFI, BPFO), acceleration,  temperature. 
    • Electrical data: Motor current signatures, load profile, power quality, torque. 
    • Process data: Steam pressure, black liquor firing rate, freeness, consistency, sheet moisture, grade  and schedule.

    Rather than surfacing a bearing anomaly in isolation, PlantOS™ evaluates it in the context of motor load,  upstream process stability, and upcoming production events – and recommends action that addresses  the system, not just the component.

    Energy Efficiency — Reliability and Energy, Solved ogether 08

    In pulp and paper, where thermal and electrical energy together dominate the cost base, every minute  of unstable operation taxes kWh/ton and steam/ton. Recovery boiler load fluctuations, refiner  instability, and dryer-section disturbances create cascading thermal and fibre losses — inefficient steam  generation, over-refining compensation, and reheating penalties across the machine. 


    Reliability and energy efficiency are the same problem, solved in tandem. PlantOS™ stabilizes critical asset reliability by detecting faults early — whether mechanical, electrical, or process-induced — and  prescribing corrective action before thermal and fibre losses compound: 

    • Smoother runs: Fewer interruptions mean better steam balance and less energy wasted in start up and stabilization cycles. 
    • Higher throughput per energy block: More tons produced within the same scheduled energy  window, improving effective energy intensity. 
    • Lower specific energy on refiners: Plate and bearing interventions aligned to the wear-and efficiency inflection, not the calendar. 

    Every fault avoided on a boiler auxiliary, refiner, or dryer section is a reliability gain and an energy gain in  the same action — making sustainability claims operationally credible and financially defensible. 

    What This Means for Mill Leadership 09

    For a Paper Mill Head, Reliability Engineering, and Digitalization teams, Prescriptive AI-powered closed loop reliability is now a strategic lever, not just a maintenance tactic. 


    With PlantOS™ orchestrating agentic, explainable AI across recovery boiler, refiner, and paper machine  operations, mills achieve: 

    • Decisions operators execute: AI-assisted prescriptions replace guesswork with high-accuracy fault  prediction, explainable evidence, and 99%+ operator action rates. 
    • Direct KPI linkage: Reliability actions measurably improve MTBF, MTTR, and kWh/ton –making  production outcomes an operational reality. 
    • Scalable reliability playbook: Standardized prescription templates, thresholds, and parts lists  across machines, mill sites, and grades – eliminating site-to-site variation.
    •  Proven, fast payback: Payback in 6–12 months, against an 18–24 month industry norm for digital  projects.

    This enables semi-autonomous mill operations where vertical AI, orchestrated end-to-end, handles  diagnostics and prescriptions across mechanical, electrical, and process-induced faults – freeing COO,  CFO, CDO, Maintenance Managers, Energy Managers, reliability experts for strategic oversight and  delivering safer, more profitable, and more sustainable pulp and paper production.

    Frequently Asked Questions


    How is Prescriptive AI different from predictive maintenance on the recovery boiler and paper machine?

    Predictive maintenance flags that a component may fail soon but rarely tells you exactly what to do,  when, and with what expected business impact. Prescriptive AI on PlantOS™ goes further – delivering an  explainable report that names the fault, specifies the action and timing, and quantifies the business  outcome. Operator action rates consistently exceed 99%, because the evidence behind every  prescription is visible and auditable. 


    Can PlantOS™ work with our existing sensors and control systems?

    Yes. PlantOS™ ingests data from existing condition monitoring systems, PLC, DCS, historians, and third  party sensors on recovery boilers, refiners, paper machines, and auxiliary equipment. It layers vertical AI  models and the 99% Trust Loop on top – without forcing a rip-and-replace hardware strategy.


    How does this support your sustainability and decarbonization targets?

    By reducing unplanned stoppages, fibre losses, and energy excursions, PlantOS™ helps you produce  more tons within the same or lower energy envelope, improving kWh/ton, steam/ton, and associated  emissions intensity. These improvements are operator-validated and auditable – credible inputs into  sustainability reporting and customer commitments. 


    What kind of results have mills seen with the 99% Trust Loop?

    User-validated prescriptions across pulp and paper sites — including Satia Paper Plants, Al Dafrah Paper,  Ankutsan Paper Mill in Turkey, and more — have delivered 2788 hours of unplanned downtime saved  per single intervention on critical assets across 28 Paper Mills globally, with payback consistently inside  6–12 months. Across PlantOS™’s global footprint spanning nine industrial verticals, 881 Plants the  platform has eliminated over 140,641 hours of unplanned downtime.

    See the outcomes for yourself.

    Explore how PlantOS™ is delivering semi-autonomous operations across pulp and paper mills.

    Thank you for your interest in PlantOS™ Prescriptive AI.

    Enter your official work email to unlock the World’s Most User-Validated Case Study.[contact-form-7 id=”93f3a5d” title=”pdf downlaod-blog-Plant Reliability Beyond Mechanical Faults”]

    Read More on Prescriptive AI

  • Prescriptive AI for Low-Speed, Hygiene-Critical Assets in Pharma and F&B: Beyond Traditional Condition Monitoring

    Prescriptive AI for Low-Speed, Hygiene-Critical Assets in Pharma and F&B: Beyond Traditional Condition Monitoring

    Prescriptive AI for Low-Speed, Hygiene-Critical Assets in Pharma and F&B : Beyond Traditional Condition Monitoring

    Why auxiliary equipment like mixers, blenders, and packaging lines are often overlooked in reliability programs — and how prescriptive AI brings them into focus.

    Read Time: 8 minutes  | Author – Kalyan Meduri

    Split industrial image showcasing pharmaceutical processing equipment and a food and beverage bottling line, representing low-speed, hygiene-critical assets monitored by PlantOS™ prescriptive AI for improved reliability, compliance, and condition monitoring.

    A pharmaceutical mixer turning at 8 RPM doesn’t announce its failure the way a high-speed compressor does. There’s no dramatic spike in vibration amplitude. No alarm that triggers an automatic shutdown. Instead, the failure creeps in – a subtle bearing degradation that goes unnoticed for weeks, until a batch worth $500K fails content uniformity testing and triggers a deviation report.


    This is the daily reality for QA-aligned Maintenance Managers, Pharma Engineering Heads, and F&B Operations Leaders managing low-speed, hygiene-critical assets. These machines –mixers, blenders, agitators, ribbon dryers, and packaging lines – sit at the intersection of process reliability, product quality, and regulatory compliance. And they are precisely the assets that traditional online condition monitoring struggles to cover.

    The Low-Speed Monitoring Problem Nobody Wants to Talk About

    Here’s why the industry has a blind spot.


    Conventional vibration-based condition monitoring systems are designed for machines running at 600 RPM and above. At those speeds, bearing defects generate strong, repeatable vibration signatures that algorithms can detect and trend with reasonable confidence. Drop below 100 RPM – or down to the 2–25 RPM range common in pharmaceutical ribbon blenders, F&B agitators, and tablet coating pans – and the physics change entirely.


    Blind Spot
    Grey Zone
    Conventional Monitoring

    02
    RPM
    100
    RPM
    600
    RPM
    3900
    RPM


    Ribbon Blenders
    5 – 15 RPM
    Coating Pans
    2 – 12 RPM
    Agitators
    8 – 30 RPM

    Compressors
    1500+ RPM
    Pumps
    1000+ RPM

    PlantOS™ Coverage: 2 – 3900 RPM


    At low speeds, the energy released from a bearing defect decreases dramatically. Defect repetition frequencies fall into the noise floor. Signal-to-noise ratios collapse. Standard accelerometers and data collectors either miss the fault entirely or bury it in background vibration from adjacent equipment. Most systems that claim low-speed asset monitoring are, in practice, collecting data but not diagnosing anything actionable.


    This leaves reliability teams in a bind: the assets most critical to batch integrity and compliance are the very assets their monitoring infrastructure cannot reliably cover.

    Why Pharma and F&B Can’t Afford the Gap

    In most heavy industries, an equipment failure means lost production hours and repair costs. In pharmaceutical manufacturing and food & beverage processing, the consequences compound in ways that no Equipment & Process monitoring dashboard fully captures.


    Macro-Crisis Diagram


    How a micro-failure becomes a macro-crisis

    Bearing wear
    Undetected at low RPM

    Intercept here
    What prescriptive AI prevents
    Early detection at 2 RPM → Prescription delivered → Bearing replaced during CIP
    Zero batch loss · Zero deviation · Full audit trail

    Batch failure
    $500K–$2M per lot

    Deviation + CAPA
    Investigation opened
    Audit trail gap
    Escalating cost, regulatory exposure, and reputational damage →

    FDA 483
    Warning letter
    Production halt
    Consent decree

    Batch loss is the first domino. A mixer bearing failure mid-batch doesn’t just stop production – it contaminates or compromises an entire batch of active pharmaceutical ingredient or food product. In pharma, a single rejected lot can cost $500K to $2M. In F&B, perishable raw materials compound the financial hit with spoilage that cascades across the production schedule.


    Compliance exposure is the second. Under 21 CFR Part 211 and EU GMP Annex 1, equipment used in drug manufacturing must be maintained within validated operational parameters, with every deviation documented and investigated. An undetected equipment degradation that affects product quality doesn’t just produce a failed batch – it produces a formal deviation, a CAPA investigation, and potentially an FDA Form 483 observation. For F&B, FSMA and HACCP requirements create comparable audit exposure.


    Hygiene constraints amplify the difficulty. These assets operate in washdown and clean-in-place (CIP) environments where physical access is restricted, manual inspections are limited by sanitation protocols, and route-based data collection introduces contamination risk. The very environments that demand the highest reliability are the hardest to monitor using traditional approaches.

    What Prescriptive AI Changes – And What It Doesn’t

    The market noise around “AI-powered condition monitoring” is growing, but most of what’s being offered is still predictive at best — flagging that a fault exists, then leaving the maintenance team to figure out what to do about it.


    Prescriptive AI takes a fundamentally different approach. Instead of stopping at an alarm, it delivers a specific, actionable recommendation: what is failing, why it matters in the context of the current process, and exactly what maintenance action to take.


    PlantOS™, Infinite Uptime’s prescriptive AI platform, operationalises this through what it calls the 99% Trust Loop – a closed-loop cycle of fault prediction, prescriptive recommendation, operator validation, and outcome tracking. The loop works like this: raw sensor data is contextualised by vertical-specific AI models trained on industry failure modes → a fault prediction is generated with 99.97% Prediction accuracy → a specific prescription is delivered to the operator → the operator validates and executes → the outcome is tracked and fed back into the model.


    PlantOS Trust Loop


    Traditional predictive
    Sensor data
    Vibration, temp
    Alert generated
    Fault detected
    Now what?
    Team interprets
    Maybe acts
    No tracking
    Loop never closes

    PlantOS™

    Prescriptive AI — the 99% Trust
    Loop

    Sensor data
    Continuous, 2+ RPM
    AI contextualises
    Equip + process data
    Prescription
    What, when, why
    Operator validates
    99% act on it
    Outcome tracked
    Audit-ready log

    Feeds back
    into model


    The key differentiator isn’t just Prediction accuracy. It’s that operators trust it enough to act on it – 99% of PlantOS™ prescriptions are acted upon, a number validated across 881 plants and 9 industrial verticals.

    How PlantOS™ Solves Low-Speed Asset Monitoring

    PlantOS™’s sensing architecture is built to handle the exact conditions that defeat conventional systems.


    Data Contextualization Diagram


    Single source of truth: Equipment + Process Data Contextualization


    Equipment data
    Bearing vibration
    Temperature
    RPM / motor current
    Acoustic profile

    Process data
    Batch parameters
    Pressure differentials
    Temperature profiles
    Blend homogeneity

    PlantOS™ AI
    Vertical AI models
    99.97% accuracy

    Prescription
    Replace mixer bearing
    before next API blend
    Schedule during CIP
    Audit log: auto-filed

    Generic alert: "Bearing degradation detected" → Prescriptive: context-aware action with traceability

    Monitoring assets as slow as 2 RPM. PlantOS™’s wired piezoelectric sensing nodes deliver continuous online condition monitoring across an operating range of 2 RPM to 3,900 RPM. Unlike wireless sensors that sample intermittently and miss transient fault signatures, continuously powered sensors capture the full acoustic and vibration profile – even at speeds where traditional accelerometers produce nothing usable. This is what makes monitoring pharmaceutical ribbon blenders, F&B agitators, and low-speed coating pans practically viable for the first time.


    Equipment + Process correlation. PlantOS™ doesn’t treat equipment health in isolation. It correlates equipment data – bearing vibration, temperature, RPM – with process data like batch parameters, pressure differentials, and temperature profiles. A bearing anomaly in a mixer isn’t evaluated in a vacuum; it’s assessed in the context of the current batch composition, process stage, and quality-critical parameters. This is the difference between an alert that says “bearing degradation detected” and a prescription that says “schedule bearing replacement before the next API blending cycle to avoid content uniformity deviation.”


    Audit-ready traceability. Every prediction, prescription, operator action, and outcome is logged with timestamps and user validation. For pharma teams operating under 21 CFR Part 211 and GMP documentation requirements, this isn’t a nice-to-have – it’s the difference between an equipment maintenance programme that supports audit readiness and one that creates regulatory exposure. PlantOS™’s Prescription Engine generates a traceable, tamper-evident record of every maintenance decision, directly addressable in deviation investigations and CAPA documentation.


    The Prescriptive Difference on the Shop Floor

    In a typical F&B scenario: a ribbon blender operating at 15 RPM with bearings that traditionally get replaced on a fixed calendar schedule – say, every six months. With PlantOS™, the system detects early-stage outer race degradation at month three, correlates it with an increase in motor current draw and a subtle shift in blend homogeneity data from the process historian, and prescribes a bearing replacement during the next scheduled CIP cycle – not before (which would interrupt production) and not after (which risks batch contamination).


    The result: zero unplanned downtime, zero batch loss, and a documented maintenance action that aligns with the plant’s compliance framework.


    Now scale that across every mixer, agitator, blender, and packaging line in a facility. The math on ROI stops being theoretical very quickly. 


    Across its installed base, PlantOS™ has eliminated over 140,641 hours of unplanned downtime and avoided over 15,200 breakdowns — with a typical payback of 6–12 months against an industry norm of 18–24 months for digital transformation projects.

    What to Look for in a Low-Speed Monitoring Solution

    Not every condition monitoring platform is built for this challenge. When evaluating solutions for low-speed, hygiene-critical assets, the questions that matter are: 


    Evaluation framework: low-speed monitoring solutions

    Criteria
    Ask this
    Why it matters

    Continuous sensing
    below 25 RPM
    Wired or wireless?
    Continuous or sampled?
    Intermittent sampling
    misses transient faults

    Prescriptive output
    not just alerts
    Does it tell you what
    action to take?
    Alerts without actions
    = interpretation burden

    Equip + process
    correlation
    Does it link machine
    health to batch data?
    Siloed diagnostics miss
    process-level impact

    GMP audit trail
    21 CFR / FDA ready
    Auto-logged or manual
    documentation?
    Manual records = audit
    gaps and human error

    Operator trust
    action rate
    What % of recommendations
    are acted upon?
    Low trust = shelfware
    High trust = real ROI


    These are the questions that separate meaningful low-speed asset monitoring from marketing claims.

    Frequently Asked Questions


    1. What makes low-speed asset monitoring different from standard condition monitoring?

    Standard online condition monitoring relies on vibration signatures that are strong and repeatable at higher speeds. Below 100 RPM, fault-generated energy drops significantly, defect frequencies blend into background noise, and conventional accelerometers often can’t distinguish a developing fault from normal operation. Effective low-speed monitoring requires specialised sensing hardware, advanced signal processing, and AI models trained specifically on low-speed failure modes.


    2. Can prescriptive AI reliably monitor equipment operating at speeds as low as 2 RPM?

    Yes. PlantOS™ uses continuously powered wired piezoelectric sensors that capture full vibration and acoustic profiles across a range of 2 RPM to 3,900 RPM. Unlike intermittent wireless sampling, continuous monitoring ensures transient fault signatures at very low speeds are not missed – enabling reliable diagnostics on assets like pharmaceutical ribbon blenders and F&B agitators.


    3. How is prescriptive AI different from predictive maintenance?

    Predictive maintenance tells you that a failure is developing. Prescriptive AI tells you what is failing, why it matters in your specific process context, and exactly what action to take – including when to schedule it to avoid batch disruption or compliance exposure and the business outcomes that will get impacted at scale. The 99% Trust Loop closes this gap by tracking whether prescriptions are executed and feeding outcomes back into the model.


    4. How does this PlantOSTM approach handle GMP and FDA compliance requirements?

    Every prediction, prescription, operator validation, and maintenance outcome is automatically logged with timestamps, creating a fully traceable audit trail. This documentation is designed to support 21 CFR Part 211 requirements, deviation investigations, and CAPA processes — without requiring manual record-keeping workarounds that introduce human error and audit risk.


    5. Some vendors claim AI-based condition monitoring for low-speed assets. How do I evaluate whether a solution actually works at low speeds?

    Ask three questions: Does the system use continuous (not intermittent) sensing at low RPMs? Can the vendor demonstrate diagnostic accuracy — not just data collection — below 25 RPM with validated outcomes? And does the platform deliver specific maintenance prescriptions, or just alerts and alarms that require your team to interpret? Many solutions collect data at low speeds but lack the AI models and signal processing to extract actionable diagnostics from it.


    6. What types of hygiene-critical assets can prescriptive AI monitor in pharma and F&B?

    PlantOS™ monitors a wide range of rotating equipment in regulated environments, including mixers, blenders, agitators, ribbon dryers, coating pans, granulators, packaging line drives, conveyor systems, and HVAC components critical to cleanroom and controlled-environment operations.


    7. What ROI can we expect, and how quickly?

    PlantOS™ deployments typically achieve payback within 6–12 months — compared to the 18–24-month norm for industrial digital transformation projects. ROI is driven by eliminated unplanned downtime, avoided batch losses, reduced spare parts inventory through planned replacements, and lower compliance remediation costs.


    8. Does prescriptive AI replace my existing maintenance team or CMMS?

    No. Prescriptive AI augments your existing reliability and maintenance infrastructure. PlantOS™ integrates with existing CMMS and process control systems, delivering prescriptions into your team’s existing workflow. The platform’s value is in reducing the interpretation burden on your engineers — giving them fewer, clearer, higher-confidence calls to act on rather than more data to sift through.

    Ready to close the reliability gap on your most challenging assets?
    Talk to our Team of experts at infinite-uptime.com

    Read More on Industrial Energy Efficiency